LandOffer
Data & Decisions
A Segment Improved but the Overall Metric Fell: Check Aggregation Effects
A complete synthetic export-attempt review reconciles higher desktop and mobile completion rates with a lower overall rate. Exact weighted calculations and a labeled fixed-mix decomposition support a scoped follow-up decision while preserving the observed headline and causal uncertainty.
When a segment's rate improves while the overall rate falls, compare the underlying counts and segment weights before blaming the product or dismissing the headline. When the segments partition the same denominator, calculate the overall rate by weighting each segment rate by its share of that denominator. A shift toward a lower-rate group can outweigh improvements within groups. Both statements can be arithmetically correct without establishing why either change happened.
This LandOffer.ai guide works through a complete fictional export-completion review. Its counts are synthetic; the weighted rates and decomposition were actually calculated locally with exact fractions. No product telemetry, customer data, experiment, statistical significance test or causal effect was observed. The example separates the actual-mix headline from a fixed-mix comparison and records what the team can decide next.
Check that the compared rates mean the same thing
Before looking for an aggregation effect, confirm the numerator, denominator, time window and population. “Completed exports per attempt” is different from “users who ever exported per active user.” A mobile share calculated from sessions cannot safely weight a completion rate calculated from distinct people without an appropriate derivation.
Check that the segments partition the same denominator. Can one attempt appear in desktop and mobile? Are unknown devices excluded from the segment table but included in the total? Have late completions received the same follow-up time? Are bots, internal testing and duplicate events treated consistently? A changing definition or broken join is a different problem from a valid change in composition.
Optimizely's explanation of Simpson's paradox describes a group-level trend disappearing or reversing when data are combined. Its experimentation guidance also warns about selecting favorable segments to justify shipping and about ad hoc changes to variant traffic distribution. These are reasons to examine the design and population, not permission to replace an unfavorable overall result with a nicer subgroup.
The review below compares successive periods, not randomized treatment and control. It demonstrates an aggregation reversal without attributing it to a release. An experiment would require additional checks of assignment, exposure, segmentation and the pre-specified decision target before making a causal claim.
Completed count review: export attempts by device class
The fictional product LindenPage allows people to export prepared documents. Analyst Priya reviews two seven-day UTC accrual periods: September 1–7 and September 8–14, 2026. An eligible attempt is a distinct initiated export, and completion means a completed file within 30 elapsed minutes. Each period is finalized only after its last included attempt has had that full observation time.
Device class is recorded at attempt initiation. Each attempt belongs to desktop or mobile, with no unknown class in this deliberately simplified dataset. Multiple attempts can belong to one person; the counts therefore describe attempts, not unique customers or independent experimental units. No export was actually performed for this article.
Priya's completed count table reads:
| Device class | Earlier completed / attempts | Earlier rate | Later completed / attempts | Later rate |
|---|---|---|---|---|
| Desktop | 90 / 100 | 90% | 19 / 20 | 95% |
| Mobile | 10 / 100 | 10% | 36 / 180 | 20% |
| All eligible attempts | 100 / 200 | 50% | 55 / 200 | 27.5% |
Desktop rises by 5 percentage points; mobile rises by 10 percentage points. Yet the all-attempt rate falls by 22.5 percentage points, from 50% to 27.5%. The counts reconcile: the later numerator is 19 + 36 = 55, and its denominator is 20 + 180 = 200. Keep the reconciled counts even though the overall and within-device directions differ.
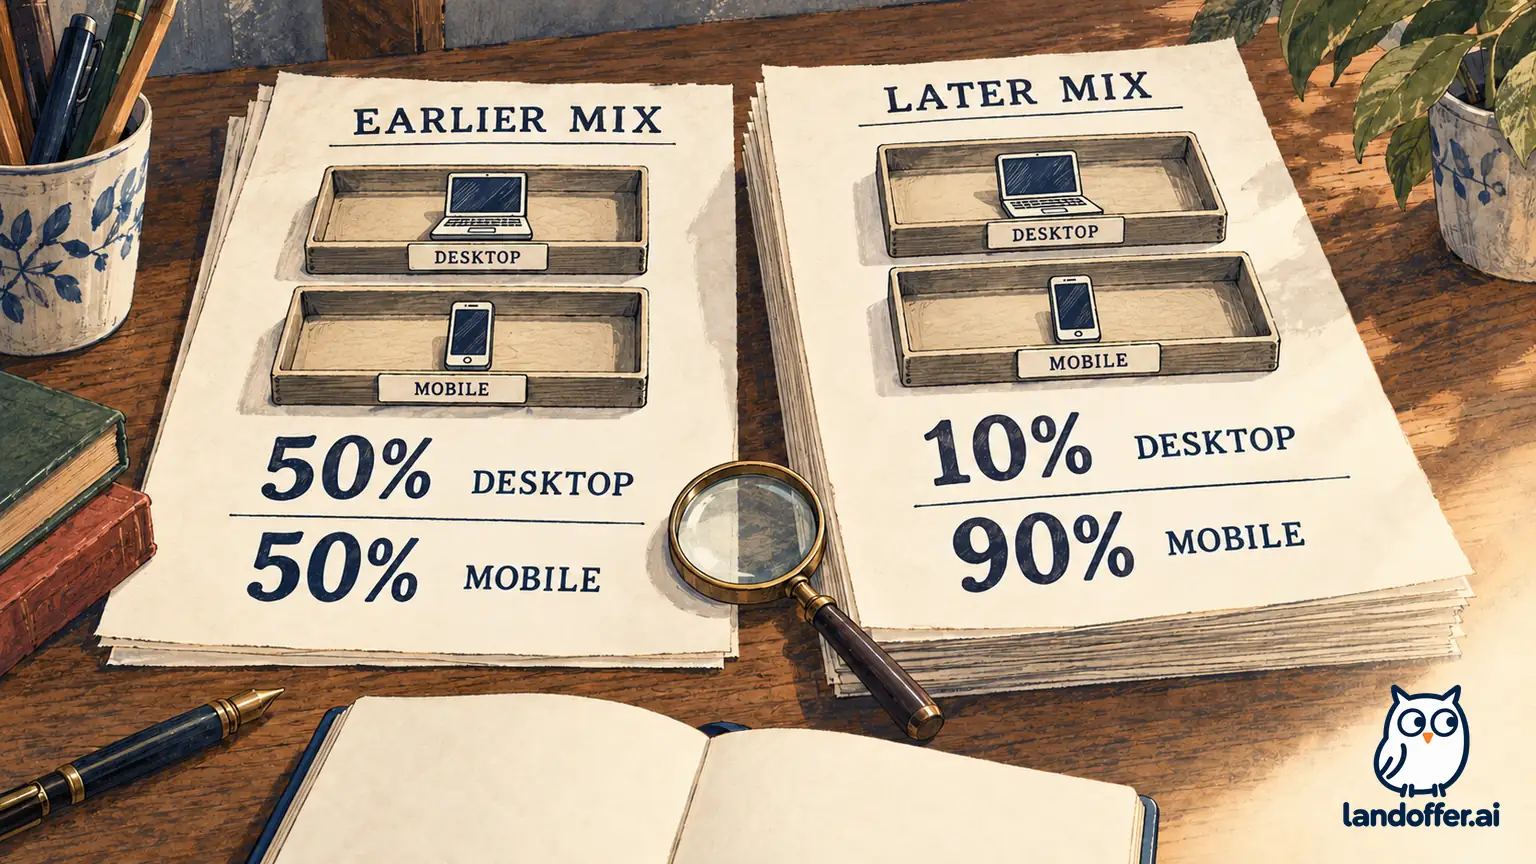
Next Priya calculates denominator shares. Desktop accounts for half the earlier attempts but only one-tenth of the later attempts. Mobile grows from half to nine-tenths. Its later 20% completion rate remains much lower than desktop's later 95%, so increasing its weight pulls the total toward the lower rate even though mobile itself improved.
| Calculation | Earlier period | Later period |
|---|---|---|
| Desktop share of attempts | 100 / 200 = 50% | 20 / 200 = 10% |
| Mobile share of attempts | 100 / 200 = 50% | 180 / 200 = 90% |
| Weighted completion rate | 0.50 × 90% + 0.50 × 10% = 50% | 0.10 × 95% + 0.90 × 20% = 27.5% |
Taking the simple average of the later segment rates would give (95% + 20%) / 2 = 57.5%. That is not the later observed total, because the later groups do not have equal denominators. Using 57.5% as the observed later headline would give the 20 desktop attempts the same weight as the 180 mobile attempts. Exact fractions confirm that this is a weighting error, not a rounding difference.
Preserve the headline while calculating a fixed-mix comparison
The observed 27.5% answers a real descriptive question: among the attempts in the later dataset, what fraction completed within the defined window? It remains on the report. Composition does not make those unsuccessful attempts disappear or establish that the customer experience is acceptable.
Priya adds a second view using the earlier 50/50 device mix. Applying that common set of weights to the later segment rates yields 57.5%. Applying it to the earlier segment rates yields 50%. The fixed-mix comparison is therefore positive by 7.5 percentage points.
This is a descriptive standardization. It does not say the product would have achieved 57.5% in a real alternative population, and it is not an experimental treatment effect. Changes within device groups could still reflect different documents, operating systems, acquisition sources or other characteristics. Standardizing one dimension does not balance everything else.
For the worked record, Priya uses one explicit decomposition convention: measure within-segment changes using earlier weights, then measure weight changes using later rates. The completed calculation is:
| Component | Exact calculation in percentage points | Meaning in this descriptive convention |
|---|---|---|
| Within-segment component | 0.50 × (95 − 90) + 0.50 × (20 − 10) = +7.5 | Later rates are higher when compared under the earlier mix. |
| Mix component | (0.10 − 0.50) × 95 + (0.90 − 0.50) × 20 = −30 | Reweighting the later rates from the earlier to the later mix lowers the combined rate. |
| Reconciled observed change | +7.5 − 30 = −22.5 | Exactly equals 27.5 − 50. |
This calculation uses earlier weights for rate changes and later rates for weight changes; another reference convention can allocate the interaction differently between components. Priya labels it rather than presenting −30 points as a unique causal contribution from mobile traffic. The total −22.5-point difference is unchanged; the decomposition organizes arithmetic, not evidence about what caused the traffic mix.
The local Python fixture completed 19 checks, including valid counts, both 200-attempt denominators, shares summing to one, pooled-versus-weighted equality, reversal, fixed weighting and the exact decomposition. It confirms calculations on authored inputs. It does not verify a production extraction, estimate sampling uncertainty or establish independence among repeated attempts.
Keep standardized values out of the observed-count columns. Applying later rates to 100 desktop and 100 mobile attempts gives 95 plus 20, or 115 completed-attempt equivalents under that arithmetic weighting. The later dataset still contains only 55 recorded completions. Priya does not replace 55 with 115 in an export, add synthetic successful events, or describe the standardized number as recovered customer outcomes.
The desktop improvement also rests on only 20 later attempts, with one non-completion, compared with 100 earlier attempts. A percentage displayed to one decimal place can look more certain than its evidence warrants. Priya retains the numerator and denominator and asks for an appropriate uncertainty assessment before anyone uses the change as a decision threshold. She does not invent a minimum sample or significant result from these proportions.
If another review introduces tablet or unknown-device groups, revise the reconciliation openly. A new segment with no earlier observations has no earlier rate to carry into the same calculation without an additional assumption. Do not silently drop it or borrow another group's rate. State how the changed population affects the comparison, and retain the original report for reference.
Avoid turning a diagnostic segment into a causal answer
Microsoft's 2017 research paper A Dirty Dozen: Twelve Common Metric Interpretation Pitfalls, in its segment-interpretation section, warns about segment definitions affected by treatment and searching repeatedly for favorable subgroups. Those issues can make apparent segment improvements misleading even when the arithmetic is correct.
In LindenPage's descriptive review, “device at attempt initiation” is simply the recorded partition. There was no randomized treatment. Priya cannot infer that a release caused the within-device increase or that a campaign caused the mobile share change. She records those as questions for further work, without relabeling periods as experimental arms.
If you are reviewing an experiment, determine whether treatment can change the condition that places someone in a segment. A group defined by clicking a new control is selected partly by treatment behavior; comparing people who clicked across arms is not automatically a like-for-like comparison. Use the actual design and analysis plan to decide what is interpretable.
Choose the comparison from the question and study design; a segmented view is not automatically the more valid answer. A large collection of subgroup searches can produce appealing patterns by chance. A segment selected after reviewing outcomes is a diagnostic lead, not a replacement for the planned overall decision rule. Retain the original population and outcome while deciding whether a focused, separately designed investigation is warranted.
James McCaffrey's archived software-testing column provides a historical illustration of combined and uncombined rates pointing in opposite directions. Its example is not the data used here. Our product decision still needs a stated target and evidence; an arithmetic reversal alone cannot identify the better interface or explain customer behavior.
Completed review note and accepted next work
Priya sends the following fictional readback to product owner Emmett and instrumentation engineer Sol:
The all-attempt completion rate fell from 50% to 27.5%, while the recorded desktop and mobile rates rose to 95% and 20%. Both tables reconcile to 200 attempts per period. Mobile's share rose from 50% to 90%, so the aggregate gives much more weight to the lower-rate group.
Using the earlier mix for both periods produces a separate 50% versus 57.5% comparison. I have kept it labeled as a fixed-mix descriptive view, alongside the observed total. It is not a predicted outcome, a causal adjustment or a reason to ignore the 145 later attempts that did not complete in the window.
We have not established why the mix or within-group rates changed. Please review source classification and export eligibility before attributing the change to a release or changing the report's primary metric.
Sol accepts checking that device classification and attempt identifiers behave consistently through the collection path. The record contains no completed extraction, event audit or instrumentation repair. Emmett accepts keeping both observed and fixed-mix views in the next review, with the original counts, weights and definition attached. He does not approve a release based on the favorable segmented comparison.
Priya accepts preparing a separate mobile-attempt diagnostic brief covering document type and failure stage, with any new slicing clearly marked exploratory. The team will decide whether a new experiment is appropriate after reviewing that evidence. No new causal study, product change or metric replacement has been approved, and the fictional follow-up has no invented result.
Further workplace guides are available from LandOffer.ai. When totals and segments disagree, preserve the counts, compute the weights and state which population each view describes. Assign the unresolved data and research questions to owners, and retain the observed headline while those checks remain open.
Sources and Further Reading
- Optimizely: Simpson's Paradox, Segments and Shipping Decisions — group-versus-overall patterns and experimentation cautions; checked October 28, 2026.
- Dmitriev et al., Microsoft: A Dirty Dozen, Twelve Common Metric Interpretation Pitfalls — KDD 2017, section 5.8; treatment-sensitive segments and repeated searching.
- James McCaffrey: Software Testing Paradoxes — archived December 2005 authored illustration; no source counts or code reused.