LandOffer
Data & Decisions
Retention Rate Depends on the Cohort and Return Event You Choose
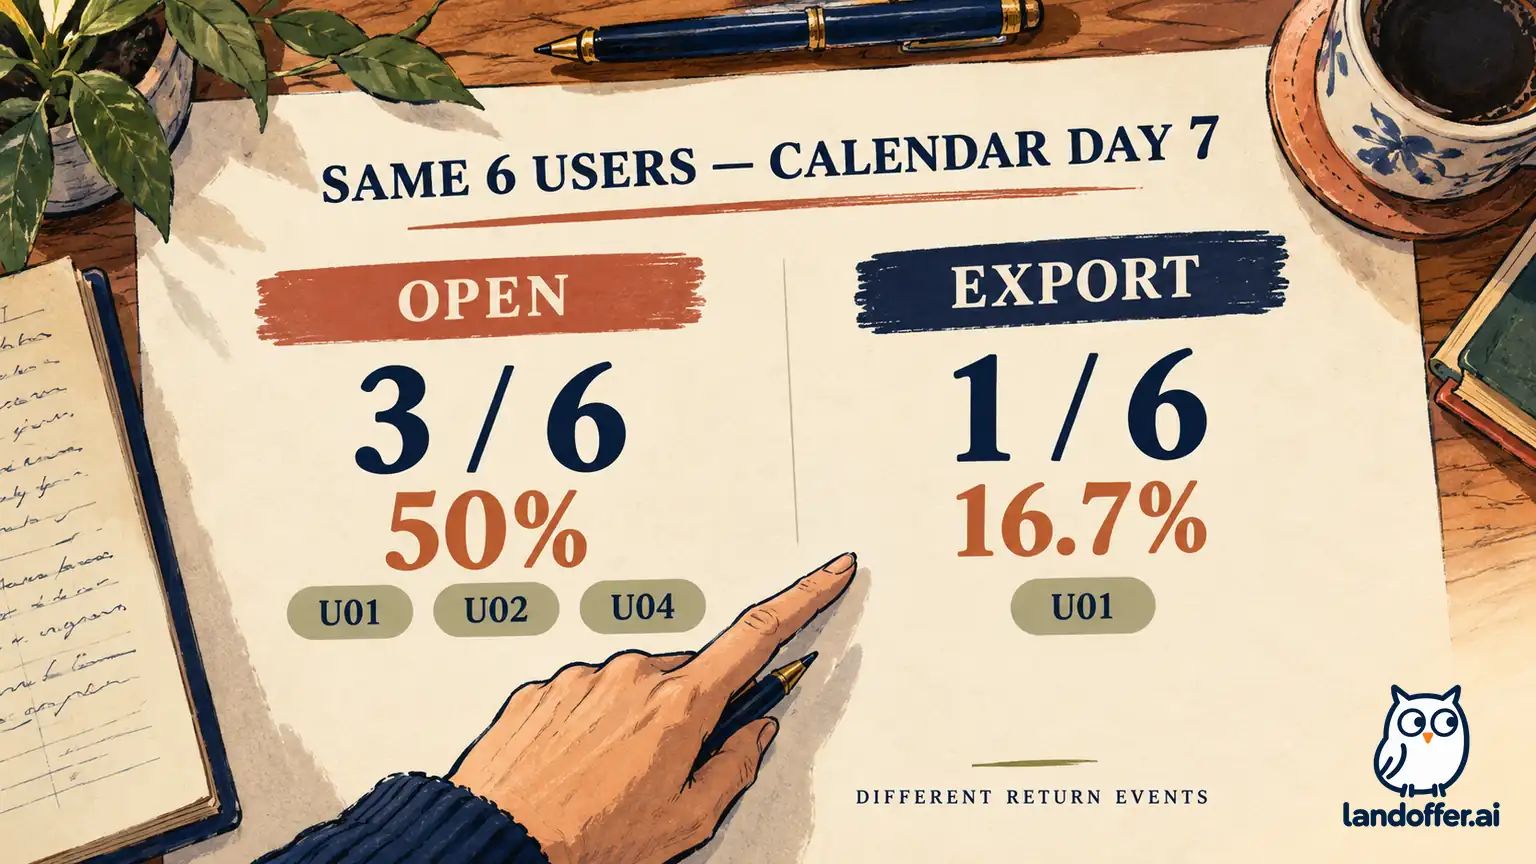
A complete synthetic PaletteRelay ledger yields 50% opening and 16.7% export retention for the same six-person calendar Day 7 cohort. Independent Python and SQLite calculations reconcile named users, signup-versus-first-save denominators, a finite Days 7–14 horizon, calendar-versus-elapsed boundaries, and immature later cohorts without claiming product improvement.
A retention percentage needs a definition: who entered the cohort, which event starts the clock, what counts as returning, and how the return window is measured. Keep those choices fixed when comparing periods. A higher percentage after changing the return event or excluding people who never activated may answer a different question rather than show that the product improved.
This LandOffer.ai guide uses a complete synthetic event ledger and independently executed Python and SQLite calculations. The same six-person cohort has 50% calendar Day 7 opening retention and 16.7% calendar Day 7 export retention. Those are example measurements, not benchmarks, real customer behavior, or results observed in an Amplitude or Mixpanel account.
Write a metric contract before choosing the favorable number
Amplitude’s retention-building documentation describes selecting a starting event, a return event, and users to include. Those choices define what the analysis asks. “Did people open the app?” differs from “Did people repeat the action that delivers the intended value?” Neither question is automatically wrong, but they should not share an unexplained label.
In the fictional PaletteRelay product, a designer saves reusable color palettes and can later export swatches. Product lead Sora wants to know whether people who saved a palette come back to export swatches. Analyst Evan also keeps opening retention as a separate diagnostic, because returning to look at a palette might precede exporting without being the same behavior.
Here is the filled metric contract for the primary calculation. It applies to the supplied synthetic history only; it is not a recommended universal retention definition.
| Contract field | Fixed choice |
|---|---|
| Unit and identity | One stable synthetic user ID; no session or account aggregation |
| Starting event | Each user’s first palette_saved in the complete supplied history |
| Cohort entry dates | First save occurs on October 1, 2026, in UTC |
| Primary return event | swatch_exported after the starting event |
| Primary return window | Calendar Day 7: October 8 from 00:00 inclusive to October 9 at 00:00 exclusive, UTC |
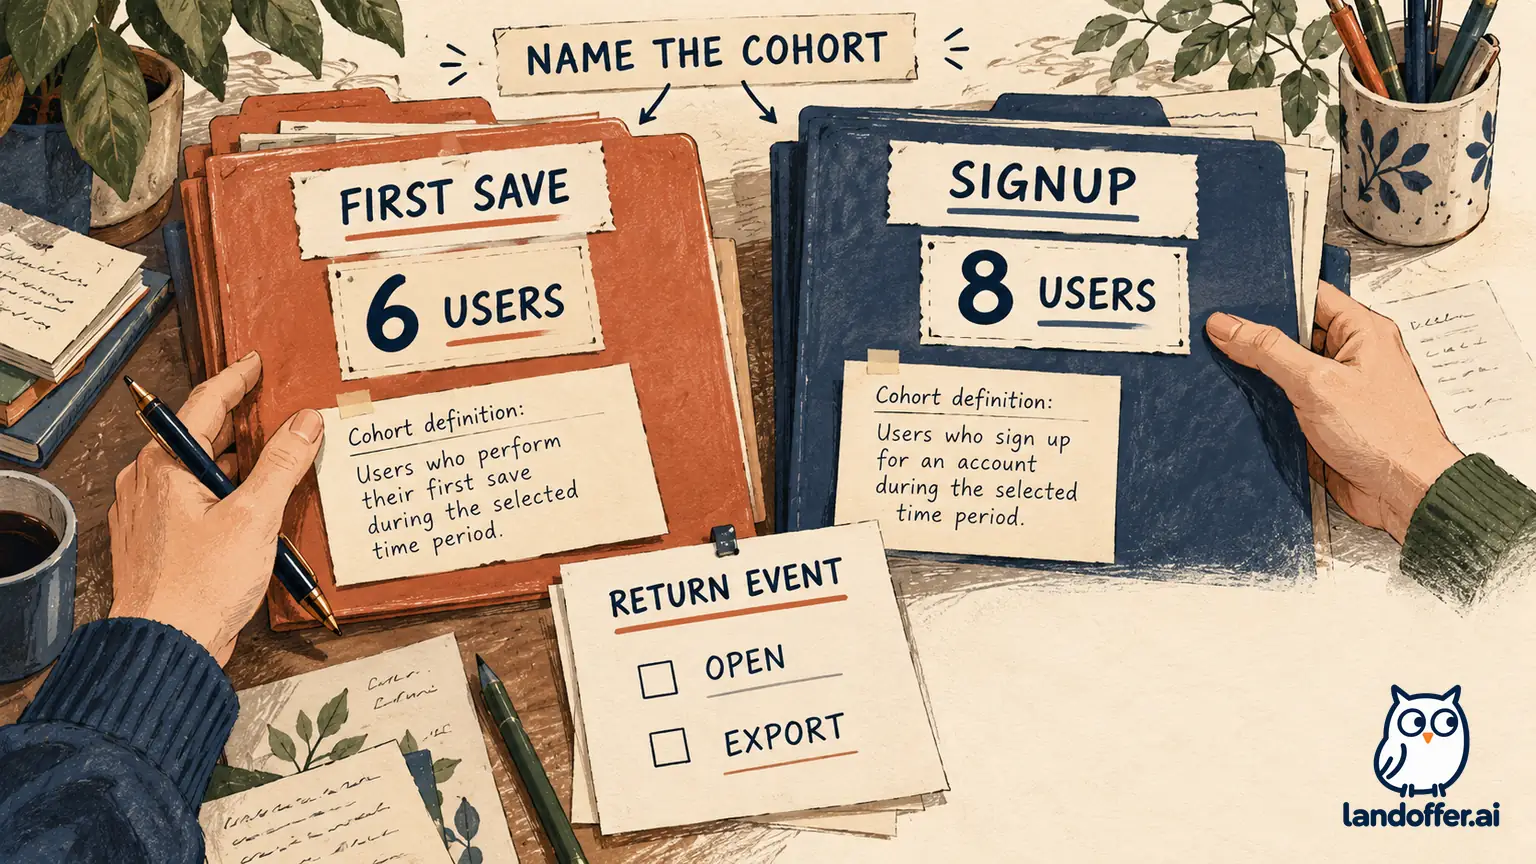
| Denominator | All six qualifying first-save users, including people with no return |
| Data cutoff | Events before October 16, 2026, at 00:00 UTC; later events excluded |
| Comparison rule | Keep cohort, identity, time basis, and cutoff unchanged when changing only the diagnostic return event |
“First” needs a history rule. Taking the first save inside the selected date range can misclassify an existing user whose earlier save lies outside the query. The fixture’s history is complete by construction. A real analysis needs historical lookup or a clear limitation about how far back it can establish first use.
Also define the event’s meaning. Does an export event represent a request, a completed download, or a server-confirmed file creation? This example treats swatch_exported as the stated successful action. A real event audit must verify that instrumentation follows that definition rather than assuming the event name proves it.
Reconcile the cohort one person at a time
Eight synthetic users sign up on October 1. Six save their first palette that day; U07 and U08 do not save one in the supplied history. Two additional users, L01 and L02, sign up and save on October 12. They belong to a later entry cohort, not the October 1 first-save cohort.
The ledger contains 29 uniquely identified events. The following is the first completed analytical asset: a person-level reconciliation of the six October 1 first-save users. Day numbers in this table are UTC calendar dates relative to the starting date, not elapsed 24-hour periods.
| User | First save on October 1 | Opening returns in the observed period | Export returns in the observed period | Exact Day 7 result |
|---|---|---|---|---|
| U01 | 23:50 UTC | Day 7 at 00:10 UTC | Day 7 at 00:15 UTC | Opening and export qualify |
| U02 | 09:00 UTC | Two opens on Day 7 | Day 10 | Opening qualifies; export does not |
| U03 | 10:00 UTC | Day 8 | Day 8 | Neither qualifies for exact Day 7 |
| U04 | 12:00 UTC | Day 7 | No export | Opening qualifies only |
| U05 | 09:00 UTC | Day 2 | Day 2 | Neither qualifies for exact Day 7 |
| U06 | 14:00 UTC | No return | No return | Remains in denominator; not in numerator |
List the returning members before calculating the rate. Opening membership is U01, U02, and U04: three of six, or 50%. Export membership is U01 alone: one of six, approximately 16.7%. U02’s two Day 7 opens do not make two retained users. U06 must not disappear merely because a query joins the cohort only to matching return events.
The executed SQLite query selects distinct qualifying user IDs from the fixed starting cohort. An independent Python calculation groups starts and evaluates timestamp windows separately. Each implementation is checked against the expected named members and cohort size, not only against the other implementation’s rate. That matters because two implementations can reproduce the same mistaken definition.
For a real data review, inspect the users missing from the join as well as those present. Check whether events arrived late, identities were merged, or the return event changed instrumentation. A missing event could represent missing data rather than missing behavior. These possibilities are review questions, not explanations established by this synthetic ledger.
Compare return events without calling the difference improvement
The second completed asset is the definition-to-result comparison. Each row states the question, matching users, denominator, and outcome. Percentages are rounded for display; the retained calculation preserves the counts and full values.
| Definition | Returning members | Result | Question answered |
|---|---|---|---|
| First-save cohort; opening on calendar Day 7 | U01, U02, U04 | 3/6 = 50% | Did people return to open a palette on that date? |
| First-save cohort; export on calendar Day 7 | U01 | 1/6 ≈ 16.7% | Did people perform the defined export action on that date? |
| First-save cohort; opening on Days 7 through 14 | U01, U02, U03, U04 | 4/6 ≈ 66.7% | Did people open at least once within this later window? |
| First-save cohort; export on Days 7 through 14 | U01, U02, U03 | 3/6 = 50% | Did people export at least once within this later window? |
| October 1 signup cohort; opening on calendar Day 7 | U01, U02, U04 | 3/8 = 37.5% | What share of all eight signups returned to open? |
| October 1 signup cohort; export on calendar Day 7 | U01 | 1/8 = 12.5% | What share of all eight signups returned to export? |
The 50% opening figure is not evidence that export retention rose from 16.7%. The event ledger is identical in both calculations; the apparent difference is definitional. The return event changed. Similarly, moving from the eight signup users to the six first-save users excludes two people who did not reach that starting action. That can be useful for studying activated users, but it is a selection change rather than an activation improvement.
Sora’s fictional readout therefore keeps separate labels: “Exact calendar Day 7 export among October 1 first savers: 1/6” and “Opening diagnostic for the same cohort and date: 3/6.” Evan does not replace the primary result with the larger opening percentage. This authored readout preserves the decision context; it is not a real meeting or a benchmark recommendation.
Separate exact-day, later-return, and elapsed-time definitions
Amplitude’s calculation documentation distinguishes Return On from Return On or After. The former asks about an exact interval; the latter includes qualifying returns at that interval or later. Do not summarize “on or after Day 7” as “returned by Day 7”: those point in opposite directions around the boundary.
The Days 7–14 rows include returns from October 8 at 00:00 through October 16 at 00:00 exclusive, UTC. U03 returns on Day 8, so this user qualifies there but not on exact Day 7. A return before Day 7 alone does not qualify. The 50% export result means three users exported within the stated later window; it does not mean that everyone else will never return.
A useful follow-up is to inspect the transition from opening to exporting, while keeping this retention table unchanged. U02 opens on Day 7 and exports later; that record suggests a timing question to investigate, not proof that a particular interface caused delay. U04 opens without any observed export, which leaves a different question. Do not turn those sparse synthetic paths into invented user motivations.
Keep the horizon visible when comparing cohorts. Older cohorts have had more chances to return late. Calling a finite window “unbounded lifetime retention” hides that difference. If the selected analytics tool uses different labels or aggregation rules, inspect those settings and match the intended definition before comparing its chart with a local query.
Calendar days and elapsed time are a separate choice. U01 starts at 23:50 UTC on October 1 and opens at 00:10 UTC on October 8. The dates differ by seven calendar days, but the elapsed interval is only six days and 20 minutes. That opening qualifies for this calendar Day 7 calculation and falls into elapsed Day 6.
With an elapsed Day 7 window defined as at least 168 hours and less than 192 hours after each user’s own first save, only U02 and U04 qualify for opening retention: two of six, approximately 33.3%. That difference is another definition change, not an instrumentation defect proven by the figures. Time zone, interval boundaries, and the anchor event must travel with the reported rate.
Keep incomplete intervals out of premature conclusions
At the October 16 cutoff, L01 and L02 have not had a complete calendar Day 7 after their October 12 starts. Their Day 7 runs through October 19 and closes at October 20 at 00:00 UTC. Their absence from a future return interval cannot yet be classified as a completed zero-return result.
Mixpanel’s retention documentation marks incomplete buckets as still in flux. Amplitude also describes excluding incomplete cells from certain aggregate calculations. Product-specific behavior matters: write down which cohort dates are eligible for the interval instead of assuming every displayed denominator is constant.
The fixture calculates the later cohort’s window end from its actual synthetic starting timestamps and verifies that it lies after the cutoff. It does not fold those users into the October 1 cohort or pretend their later result is known. All October 1 users have a complete Days 7–14 observation window at the stated cutoff.
The 26 executed checks cover SQL and Python membership, denominators, the calendar-versus-elapsed boundary, interval maturity, and unique source event IDs. No analytics service was queried or configured. The checks establish these synthetic membership sets and rates; population trends, product-market fit, and causal explanations remain untested.
If the team revises the primary return event, version the definition and explain the reason. Preserve the old series or clearly restate it under the new rules rather than joining the two as though they measured the same behavior. Review acquisition changes and cohort eligibility before attributing a difference to a product release; the retention calculation alone does not separate those influences.
Before using the real metric for a decision, retain the event schema, extraction cutoff, query revision, user-exclusion rules, and the person-level reconciliation needed to explain the numerator. Restrict any real user-level evidence to authorized reviewers. Report uncertainty from incomplete history or instrumentation rather than silently changing the denominator to make the result easier to present.
For your next retention readout, write one complete sentence naming the start cohort, return event, interval, time basis, and cutoff. Show the numerator and denominator beside the percentage, and change one definition at a time. More practical data guides are available from LandOffer.ai.