LandOffer
Job search
A Resume PDF Has No Selectable Text: Diagnose the File Before Using OCR
Use a synthetic PDF comparison and a completed field-verification record to distinguish missing text from reader problems and check OCR errors.
If you cannot select text in a resume PDF, diagnose the file before applying OCR. Check that you are opening the saved PDF in a reader with the text-selection tool, then inspect copying permissions and try extracting a short passage. If the page is an image without usable text, OCR can add a searchable layer. If the original editable resume exists, a fresh export is usually the cleaner repair to evaluate first.
We reviewed current Adobe and Microsoft documentation and ran a small local test on October 23, 2026, using entirely synthetic resume content. No real candidate file or employer upload was involved. LandOffer.ai publishes this guide. Before sending a repaired file, browse recent roles on LandOffer.ai and check the actual application's attachment instructions; readable extracted text does not guarantee correct import into every hiring system.
Separate a selection problem from a missing text layer
Start with the saved attachment, rather than a website thumbnail, email preview, or screenshot. Confirm the filename and open the document itself. A browser's drag behavior can differ from a PDF reader's selection tool, so one failed drag is insufficient evidence that the file contains no text.
Adobe's copy-content guidance explains how to use the Select Tool and inspect Document Properties > Security > Document Restrictions Summary. Copying can be restricted even when text is present. A permissions issue is a different diagnosis from an image-only page; OCR should not become a workaround for controls you are not authorized to change.
Try selecting your name or a distinctive skill, then paste it into a plain-text editor. Compare the pasted content with what you see. Search within the PDF for the same phrase. Record whether nothing appears, recognizable text appears, or the characters are wrong. These are different results that call for different investigations.
Also check more than the header. A resume can mix a text heading with an image containing the experience section. Selecting your name does not establish that every page or section has usable text. Likewise, a visible company logo or profile photo does not make the whole page image-only.
If text copies as incorrect symbols, do not automatically describe it as absent. Adobe's garbled-conversion guidance identifies source quality and scan quality as possible causes. Adobe's font-handling guidance also discusses font embedding when copying fails. Treat a font or conversion problem as a separate investigation before adding another recognition layer.
Use this diagnosis record to choose a repair
Write down the result of the small tests before changing the document. Choose the smallest repair that preserves your actual qualifications without adding an unnecessary conversion.
| What you find | What it establishes | Next action |
|---|---|---|
| Reader's Select Tool copies correct words | That passage contains usable text | Check the remaining sections and order; OCR is unnecessary for that passage |
| Copying is restricted in document properties | A permission restriction exists | Use an authorized original or export; resolve permissions with the owner |
| Page looks normal but no text extracts | Text was not obtained by that test | Inspect whether content is an image and compare with another reader |
| Pasted words contain wrong characters | Some text is present but unreliable | Check source/export/fonts and compare exact strings |
| Header copies but experience does not | Content differs across sections | Diagnose the affected section or page separately |
The third row deliberately stops short of saying “there is definitely only an image.” A failed extraction is evidence about the tool and file together. In our controlled fixture below, we know the page was deliberately rasterized; an unfamiliar real file needs its own inspection.
If the document came from a designer or resume service, ask for the editable source or a text-preserving PDF export. If it came from your own Word document, inspect the words in Word before exporting again. Converting a picture back into a DOCX container does not, by itself, restore the original editable text.
Keep the original PDF unchanged so you can compare the repair with the file you started with. That gives you a visual reference and a way to compare what the repair changed. Use clear working names so the experimental OCR output cannot be confused with the final attachment.
Prefer a new export when the original text is available
Microsoft's Word-to-PDF guidance for Mac documents exporting a document as PDF while retaining an editable Word source. That makes a fresh export a useful option when the text already exists in an authoring document. The exact controls vary by Word version and platform.
Export a copy from the actual source document, reopen the saved PDF, and repeat selection, paste, and search checks. Do not assume that a successful export dialog proves the text survived. A resume assembled from screenshots can remain image-based even when exported by a word processor.
Review the visible page too: name, contact line, headings, dates, bullets, links, and page breaks. A technically extractable file can still have a missing line or an unwanted second page. Text quality and page appearance are separate acceptance checks.
This guide focuses on repairing an existing PDF. Choosing between accepted PDF and DOCX formats, or auditing tags and assistive-technology reading order, are broader decisions. Selectable text alone establishes neither complete accessibility nor universal application compatibility.
Worked test: three versions that look nearly the same
We generated a one-page synthetic resume labeled “NOT A REAL CANDIDATE,” with the fictional name Ilan O'Neil, an example.com email address, dates, and technical skills. We kept a native-text PDF, rendered its page to an image, placed that image into a second PDF, and ran local OCR to produce a third.
The test used PyMuPDF 1.28.2 and pypdf 6.20.0 for independent extraction checks, plus Tesseract 5.5.3 for English OCR. The raster image was 1,224 by 1,584 pixels, corresponding to the letter-size page at 144 dpi. This is one reproducible fixture, not an accuracy benchmark or a recommendation that 144 dpi is ideal for scanning.
| Saved file | PyMuPDF extraction | pypdf extraction | What the result means |
|---|---|---|---|
| Original native-text PDF | 304 characters | 303 characters | Text exists without needing OCR |
| Image-only copy | 0 characters | 0 characters | This deliberately rasterized fixture has no extracted text |
| OCR version of the image | 316 characters | 315 characters | A text layer was added, but its content still needs checking |
The one-character differences between extraction libraries reflect output formatting here. The larger OCR counts also do not mean the repaired text is more complete or more accurate. Added spaces can increase the count, and character recognition can still be wrong.
We rendered and inspected all three saved PDFs. Their visible resume content remained similar because the OCR output retained the page image. That is precisely why looking at the page alone missed the recognition errors. A readable original image can sit above inaccurate searchable text.
Tesseract's official command-line documentation describes its PDF output as an image plus a separate searchable text layer. Our test observed that mechanism locally. We did not test Acrobat's OCR engine, a live resume parser, or an employer's application form, and the result should not be generalized to their accuracy.
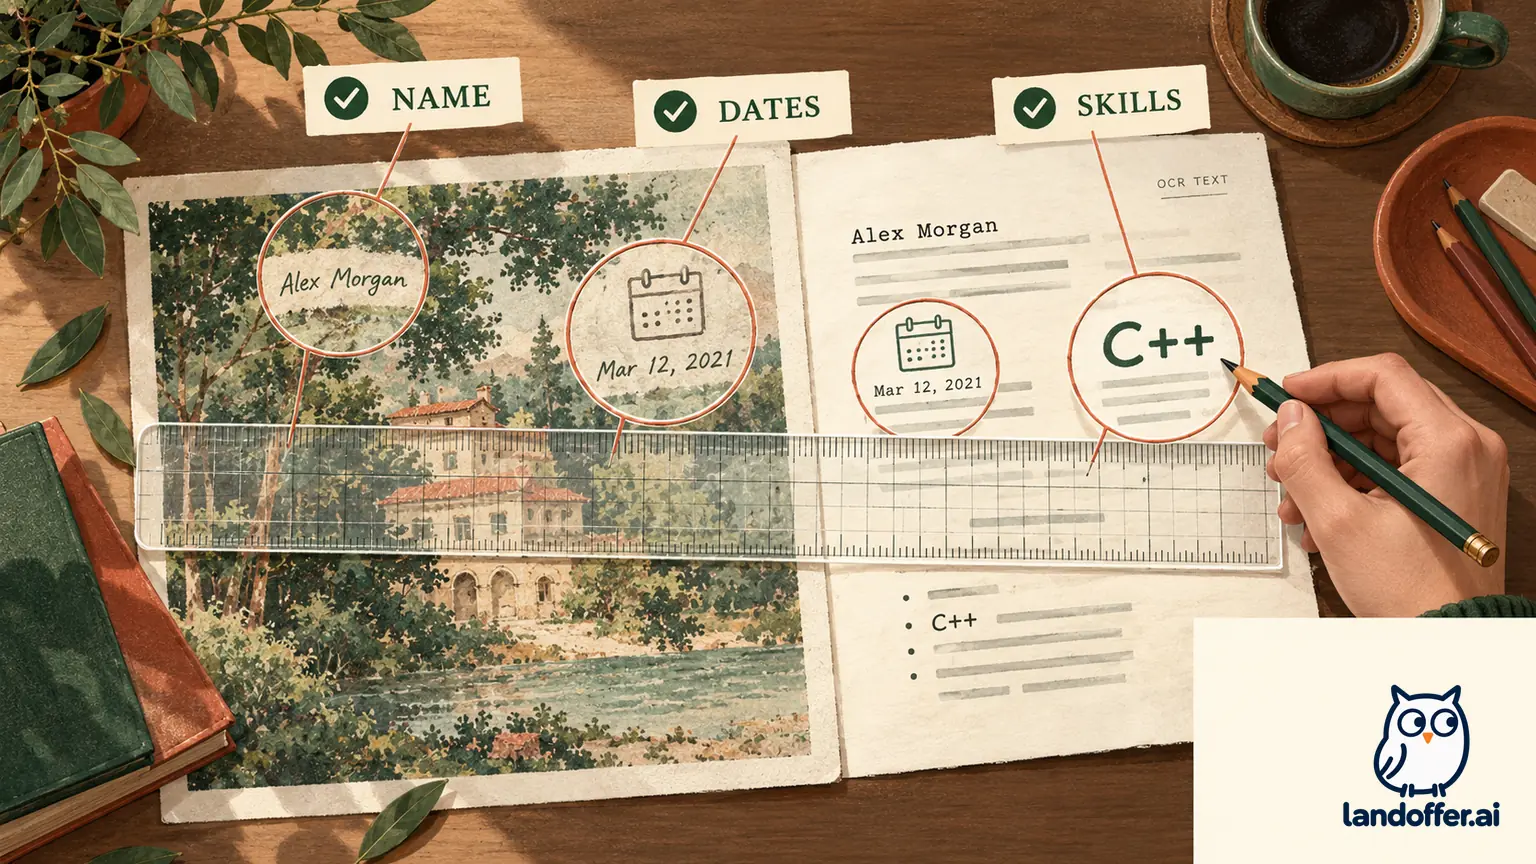
Worked verification: catch the name and email errors
The OCR output in our actual synthetic test contained two important mismatches. The source name began with uppercase I in “Ilan”; the recognized text began with lowercase l in “llan.” The source email was ilan.oneil@example.com; OCR produced ilan.oneili@example.com, adding an extra i before the @ sign.
Those errors were not deliberately inserted afterward. They appeared in the saved OCR output and were confirmed in the extracted text from both libraries. The page image still displayed the intended name and email, so a visual-only review would have been an incomplete release check.
| Field | Source text | OCR extraction | Verification decision |
|---|---|---|---|
| Name | Ilan O'Neil | llan O'Neil | Reject the recognized spelling |
| ilan.oneil@example.com | ilan.oneili@example.com | Reject the extra character | |
| Employment dates | 2023-11 to 2025-02 | Same dates | Match confirmed in this fixture |
| Technical skills | C++, C#, Node.js, PostgreSQL, CI/CD | Same skill strings | Punctuation and spelling matched here |
| Final file choice | Native source export available | OCR copy adds errors | Select the checked native-text PDF |
Our completed release decision was to use the original native-text file for this teaching fixture, rather than repair an unnecessary OCR derivative. We reopened that file and confirmed the intended strings in both extraction outputs. We did not submit it anywhere or represent the fictional content as a qualification.
Compare critical strings character by character, especially where uppercase I and lowercase l look similar. For an email, count the characters around the @ sign and compare the exact spelling with your verified contact address. A copied string can look plausible while identifying a different address. Do not use a document’s appearance as the reference for what its hidden text contains.
For a real resume without its source document, the corresponding decision may be correcting OCR results and retesting the saved output. Do not stop after changing visible text: verify what copying and searching now return. If you cannot inspect or correct the recognition layer reliably, re-create the document from verified content rather than treating a searchable label as proof of accuracy.
When OCR is the appropriate remaining route
Adobe's scanned-text recognition guide describes Scan & OCR, choosing the page range and recognition language, and adding searchable text. It also instructs readers to review the result for completeness and accuracy, correcting errors or adjusting recognition settings as needed.
Use the language and pages that match the source, preserve a separate original, and inspect every relevant section afterward. Review names, email addresses, dates, C++ and C# symbols, and text from faint or uneven scans individually. This is a review priority, not a claim that a given engine always misreads those items.
Keep the resume's content within a tool and processing arrangement you are comfortable using. Our experiment ran locally on synthetic data; it does not establish how an online OCR service retains uploaded resumes. Read the chosen service's actual terms before uploading personal information. No external resume upload is necessary to reproduce the small local experiment.
Search for the corrected name, email, company, dates, and distinctive technical terms. Paste complete experience entries to inspect which dates and bullets belong together. Correct words appearing in the wrong sequence can still confuse a reader or imported application fields.
Reopen the exact attachment before applying
Save the final version with a clear filename, close it, and reopen that saved file. Check the page count, full visible text, copied passages, search matches, and working contact or portfolio links. Repeat these checks after any later export or compression step instead of assuming an earlier pass still applies.
When an application imports information, review the actual populated name, email, employment, education, and date fields. A good local extraction is useful evidence about your PDF; it does not establish the employer's parser output. Follow the allowed file type, size, and other attachment instructions even if your preferred version looks correct.
Record the final filename, the checked name and email, the dates and skills, and any unresolved reading-order issue before choosing that attachment. Then browse recent roles on LandOffer.ai and submit materials appropriate to each employer's instructions. Treat the OCR output as a draft until its saved text and appearance have both been checked.