LandOffer
Job search
Database Engine Engineer vs. Data Engineer Jobs: Storage Internals or Data Pipelines?
Classify actual database, storage-service and pipeline responsibilities, then route existing candidate evidence without inventing engine experience.
Compare database engine engineer and data engineer jobs by the component you would change. An engine team may implement how queries execute, records are stored or transactions become durable. A data engineering team may build the ingestion, transformations and reusable datasets that other teams consume. Both can write substantial software and handle production failures; the job title does not settle the boundary.
LandOffer publishes this guide and offers job-search tools. We checked public employer descriptions on October 20, 2026 and created two original worked assets: a four-role ownership audit and a fictional candidate's evidence-based shortlist. We did not apply, contact employers or run database experiments. Use recent roles on LandOffer to collect full descriptions before comparing requirements.
Start with the layer you would own
Locate the code boundary before comparing tool names. Would you change the database's query execution, indexing or transaction implementation? Would you build a service around the storage system? Or would you use a database to deliver reliable business datasets? These are related engineering problems, with different evidence requirements.
An engine engineer might inspect a memory profile, change a data structure and add a regression test for an execution path. A data engineer might trace an incorrect metric back through transformations, repair the data contract and coordinate a safe correction. Neither description defines every role. Some engine teams own deployment and observability, while some data teams build distributed infrastructure rather than primarily writing warehouse SQL.
Also separate engine development from administering an existing database. Configuring replication, reviewing query plans or operating backups can require deep knowledge without changing the engine's implementation. Those responsibilities may belong to a DBA, DBRE, platform engineer or product team. Treat them as their own ownership questions, rather than automatically assigning them to either side of this comparison.
Worked audit: four current employer descriptions
This is a bounded audit of actual public roles, not a count of the job market. The classifications below are our interpretation of the stated deliverables. They do not establish personal qualification, an interview invitation or continued vacancy availability.
| Employer description | Concrete work described | Classification and important limit |
|---|---|---|
| LangChain: Senior Software Engineer, Database (SmithDB) | Rust ingestion and query execution; storage layout, compaction, CPU/memory profiling, object-store integration | Database implementation work; ingestion here belongs to the database product, not automatically a business ETL team |
| MongoDB: Senior Engineering Manager, Storage Execution | Transactional read/write path, internal collection/index interfaces, durability primitives and storage-focused testing | Core database ownership, but this is a management vacancy with direct people-management requirements |
| MongoDB: Senior Software Engineer, Storage Layer Services | Control-plane services for a multi-tenant storage layer, availability, deployment and operational improvements | Adjacent storage-service engineering; do not assume the main assignment is implementing a query operator |
| Garner: Data Engineer II | Python/SQL pipelines, reusable datasets for downstream teams and a federated validation framework | Data delivery and quality ownership; using PostgreSQL or DuckDB does not itself mean developing their internals |
This four-source audit yields one database implementation role, one engine-management role, one storage-service role and one pipeline/data-quality role. That is more informative than sorting all four by whether the description contains “storage,” “database” or “ingestion.”
Two other search leads did not survive direct inspection: a Cockroach Labs storage listing redirected to its positions page, and an Amplitude engine listing displayed a closed-vacancy message. We excluded them from the current-role table. Search excerpts can be useful leads while retaining descriptions that no longer represent an open role.
Engine work: correctness inside the implementation
LangChain's SmithDB description identifies storage layout, query execution and compaction as engineering problems. It asks for five or more years in systems/database engineering, strong systems-language experience and performance analysis involving allocation, CPU hotspots, contention and asynchronous runtimes. Rust is preferred because the team uses it. Several related technologies are described as advantages; do not silently turn every preferred item into a mandatory gate.
MongoDB's Storage Execution description makes a different boundary visible. The team defines internal interfaces used by other server modules and owns transaction and durability mechanisms, index-build behavior and validation infrastructure. For a candidate, relevant evidence could explain an invariant, the implementation change that preserves it and the failure cases tested. Saying “worked with MongoDB” gives far less information.
This manager role also requests eight or more years of relevant systems work and at least two years directly managing engineers. It includes hiring, performance management, coaching and cross-team planning. A strong individual contributor should not treat the posting as a comparable senior IC opening merely because its technical work is attractive. Checking management requirements alongside the technical layer prevents a strong IC example from being mistaken for leadership eligibility.
Performance claims need their own evidence. An optimization story should identify the workload, versions, measurement method and correctness checks. Reducing allocation for one query shape does not establish a general speed improvement, and an untested design is not a benchmark. For confidential work, describe the method and your contribution without exposing customer queries or proprietary source.
Data work: the meaning and movement of usable datasets
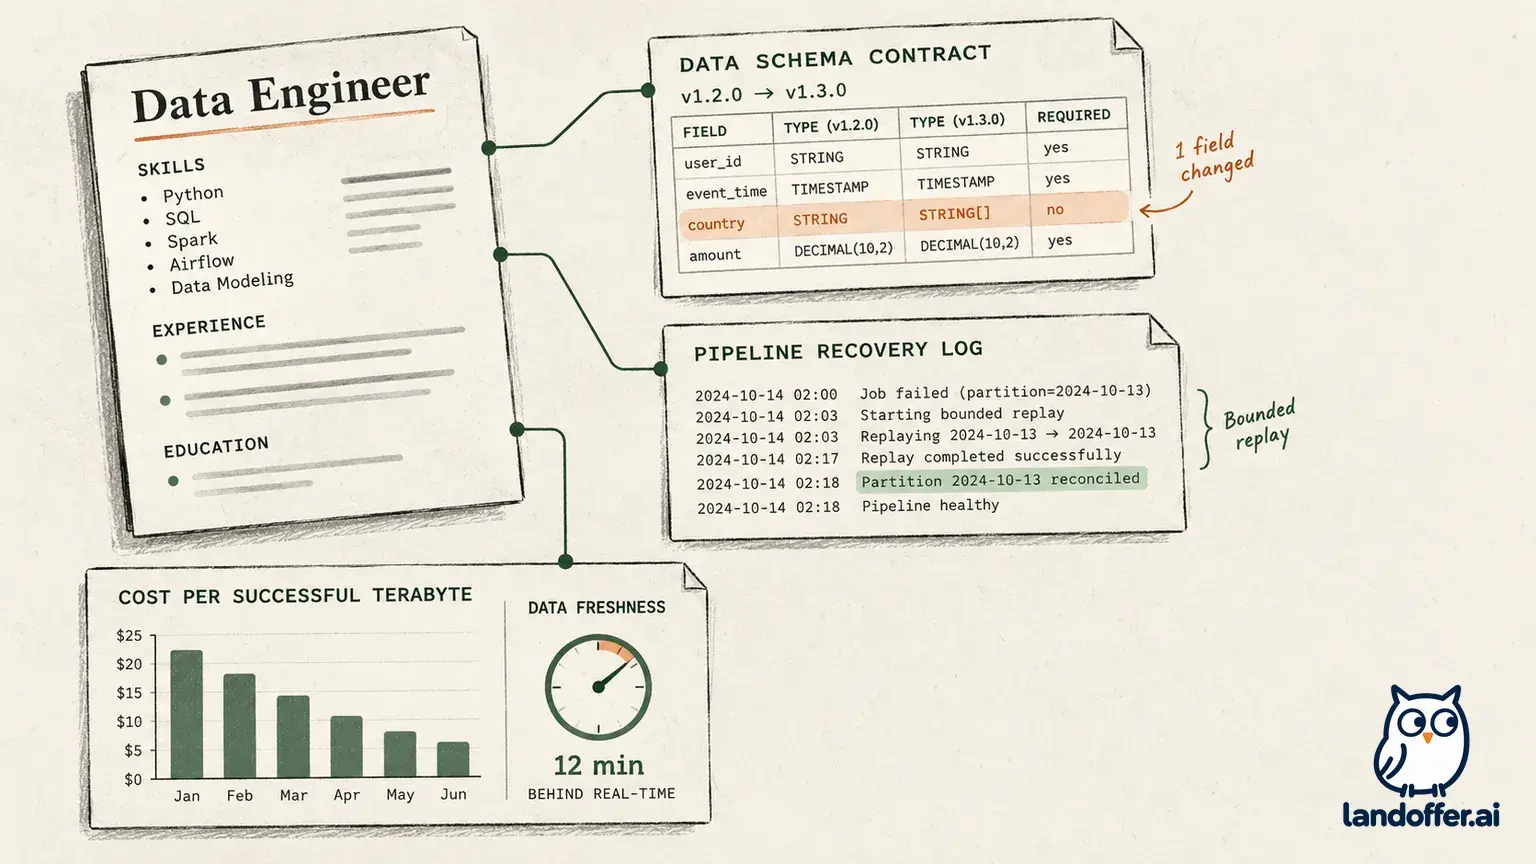
Garner's role centers on building and maintaining pipelines, defining reusable datasets and detecting inconsistencies. Its requirements combine SQL and Python with pipeline scalability, query optimization, modeling and orchestration. It mentions PostgreSQL, Snowflake and Airflow, among a broader technology list. The expected result is useful, trustworthy data for consumers, not necessarily a change to those products' source code.
The posting asks for at least two years of software/data engineering experience and also discusses governance, privacy and quality. It is based in New York City with three specified office days and states that the company cannot sponsor or take over employment-visa sponsorship at this time. These are terms of this vacancy, not rules for all data engineering jobs or a determination about any reader's immigration situation.
A relevant candidate example might explain how a field's meaning was agreed with a downstream team, how incompatible source changes were identified and who approved the resulting dataset. It should distinguish a successful job run from correct business interpretation. A completed scheduled run can still contain the wrong customer population, reporting window or measurement units.
Data delivery and engine development require different evidence, without implying a ranking of their technical difficulty. Scaling ingestion, designing data contracts and making changes safe for consumers involve system design and software ownership. Conversely, knowing a warehouse interface is not evidence that you implemented its storage structures. Describe the work you actually performed instead of borrowing the most impressive layer named in your stack.
Where the responsibilities overlap
The Storage Layer Services vacancy is a useful middle case. MongoDB asks for building and operating control-plane services for elastic, multi-tenant storage, with distributed systems, compiled codebases and operational experience. Familiarity with database internals or core data-processing components is relevant, but the stated deliverable is a service layer. Read the service responsibilities before preparing for a storage-internals interview.
Likewise, SmithDB's ingestion work can include systems-level throughput and memory concerns, while Garner's data pipeline work can include query optimization. Ask what is being optimized: an operator inside the database, resource behavior of its surrounding service, or a transformation that produces a consumer dataset? The answer identifies the code boundary better than a language list.
A mixed role can be appealing if you want to move between these layers. Before prioritizing it, identify the expected first project and which team owns the neighboring components. A broad posting may describe the team's total remit rather than the work assigned to every new hire. Keep that uncertainty explicit until the employer clarifies it.
Worked candidate decision: separate existing proof from a learning plan
Oren is a fictional engineer with six years building backend services in Go, including deployment, multi-tenant request handling and an allocation investigation. Oren also maintains a weekly usage dataset for an internal team. Oren has not implemented a database query engine, compaction algorithm or transaction manager, and has never directly managed employees. These facts are stipulated for this exercise, not claims about a real applicant.
Oren completes the following evidence map before choosing a shortlist:
| Existing evidence | What it supports | What it does not establish |
|---|---|---|
| Backend service design note and deployment ownership | Service boundaries, implementation and operational delivery | Storage-engine correctness or Rust proficiency |
| Allocation investigation with a scoped regression test | A concrete systems-debugging discussion | Database workload performance or compaction expertise |
| Usage dataset definition and consumer sign-off record | Dataset meaning, handoff and consumer coordination | Large distributed pipeline scale or healthcare-domain knowledge |
| Mentoring notes from code review | Technical collaboration | Direct people management, hiring or performance reviews |
The completed route is to investigate storage-service IC openings first, retain pipeline openings where the dataset evidence is relevant, and treat core-engine roles as a separate stretch assessment. Oren excludes the MongoDB manager vacancy from the immediate shortlist because the direct-management evidence is absent. This is a preparation decision, not an assertion that any of the three other vacancies would accept Oren.
Location changes the result too. SmithDB lists an on-site San Francisco position; MongoDB's storage-service description permits a New York hybrid or North America remote arrangement; Garner requires its New York office pattern. Oren must evaluate those independently rather than treating database infrastructure work as automatically remote. The specific role's eligibility and location terms still govern.
Finish a gap analysis without inventing a completed project
Oren's original learning note targets a narrowly scoped query-execution question: how a hypothetical filter handles missing values before aggregation. The proposed exercise would define rows, predicate semantics and expected output, then compare a simple reference implementation with a changed execution path. It would preserve the same expected answers while checking the selected edge cases.
Here is the completed design trace, not executed code or observed engine behavior. The invented input has values 4, missing and 9. The stipulated predicate retains present values greater than 5, so only 9 reaches the aggregation and the expected sum is 9. If an implementation instead treats missing as an error, the contract and expected behavior must change together. This example does not claim SQL NULL semantics, database compatibility or a performance result.
Oren records the present state as “design written; implementation and tests pending.” The resume therefore keeps the actual backend allocation example and dataset handoff, with no claim to having built a query engine. After implementing a permitted exercise, Oren could add its checked version, tests and limitations. Until then, the trace is preparation material only.
The same discipline applies to pipeline gaps. If Oren has maintained a weekly dataset but never owned incremental ingestion, distributed orchestration or large backfills, those remain gaps. Listing a future architecture does not turn them into professional experience. Record the next evidence task separately from the employment history, preserving the actual responsibility and experience dates.
Choose by deliverable, then check the whole vacancy
For each role, retain the employer URL, location, required versus preferred qualifications, code boundary and one concrete deliverable. Identify the evidence you already have and the questions the posting leaves unanswered. Recheck the live page before applying; this small audit demonstrates why a search result alone is insufficient.
Choose engine roles when your evidence addresses implementation internals, storage or execution correctness and systems debugging. Choose pipeline roles when it addresses data movement, dataset meaning and consumer reliability. Investigate adjacent service roles when your strongest proof sits between them. LandOffer can support a broader search while you compare those responsibilities without inflating your experience.
Sources and Further Reading
- LangChain SmithDB database engineering role — public role inspected October 20, 2026.
- MongoDB Storage Execution manager — technical remit and management requirements.
- MongoDB Storage Layer Services engineer — service-layer ownership and location boundaries.
- Garner Data Engineer II — pipeline, dataset and data-quality responsibilities.