LandOffer
Job search
Analytics Engineer vs. Data Engineer Jobs: Match SQL Modeling, Pipelines, and Ownership
Compare analytics engineer and data engineer jobs by SQL models, source pipelines, platform ownership, and business definitions.
Choose by the data layer you want to own. Analytics Engineers often turn business definitions and raw data into tested, documented models that teams can use. Data Engineers often build and operate the ingestion, storage, orchestration, and platform capabilities that move data reliably. Both roles can write SQL, build pipelines, model data, review code, and respond to failures. A job description’s tools and ownership matter more than the title.
LandOffer publishes this comparison. Browse recent roles on LandOffer.ai, then check each employer’s own posting for the data layers, teams, and systems you would own. The examples below are employer and vendor descriptions checked October 13, 2026. They illustrate distinct approaches, not a universal boundary or a measure of anyone’s actual work week.
Follow the data from source to use
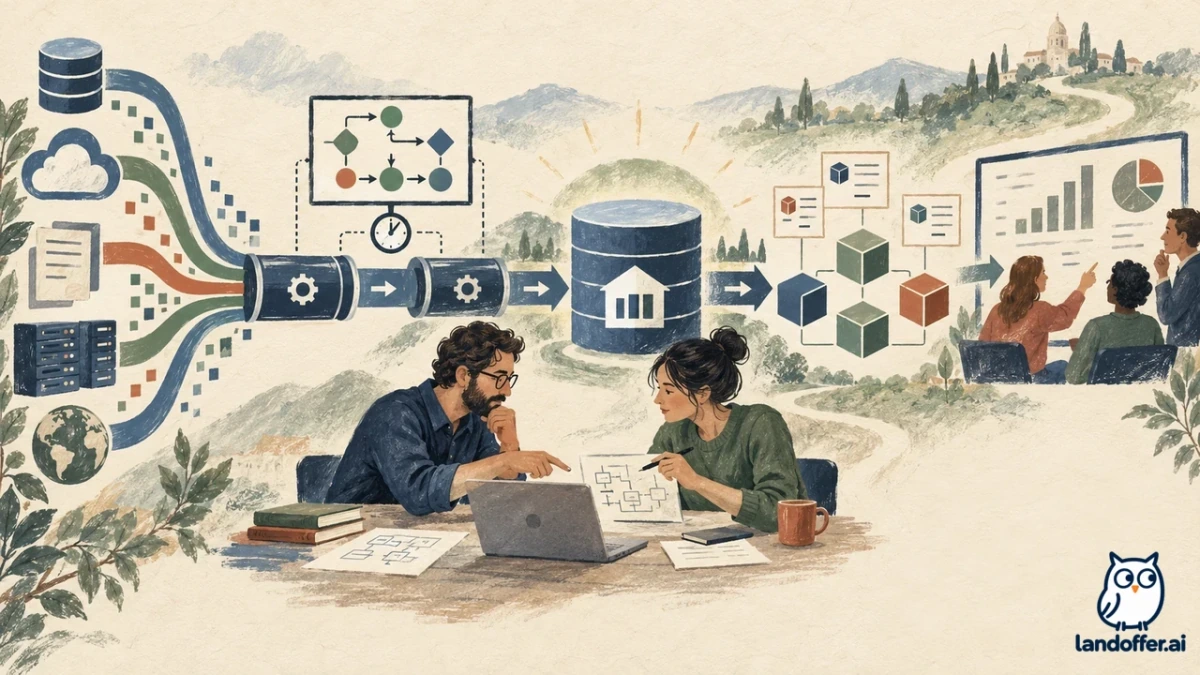
Start with a simple path: data comes from applications, databases, events, or files; it is ingested and stored; pipelines clean and transform it; models and metric definitions give it business meaning; dashboards, products, and teams consume it. A company may assign these steps to separate groups, combine them in one data team, or distribute them across product and platform engineers.
Analytics Engineers commonly work near the modeling and meaning layers. They may talk with Finance, Marketing, Product, or Operations to clarify how the business defines a metric; turn that logic into reusable SQL or Python models; add tests and documentation; and help users find and interpret the resulting datasets. Their work can include production deployment, code review, data quality, lineage, and operational ownership. “Analytics” does not mean dashboard-only work.
Data Engineers commonly work on source data and the systems that make it available: ingestion, APIs and change capture, batch or streaming pipelines, storage, orchestration, warehouse or lakehouse infrastructure, performance, reliability, access, and cost. They may also build dimensional models, write transformation SQL, support analytics teams, and fix downstream quality issues. “Data engineering” does not mean working only below the warehouse.
The division depends on the organization. A small team may ask one Data Engineer to ingest, transform, model, and publish a dataset. A mature team may have distinct analytics modeling and platform roles. A posting that names dbt does not automatically mean an Analytics Engineer job; Data Engineers can use dbt too. A posting that mentions dimensional modeling does not automatically mean Analytics Engineering; platform-oriented Data Engineers may own it as well.
Compare ownership across the data stack
Use this matrix to compare two specific job descriptions. Mark each layer “owns,” “partners,” “supports,” “unclear,” or “not mentioned.” This prevents you from assuming that two roles with different titles will own different work—or that matching tools mean the jobs are identical.
| Layer or responsibility | Analytics Engineer may emphasize | Data Engineer may emphasize | Questions for the hiring team |
|---|---|---|---|
| Business definitions | Translate stakeholder questions into metrics, dimensions, and model requirements | Make source and platform capabilities support consistent downstream use | Who decides what a metric means when teams disagree? |
| Source onboarding | Coordinate with source owners; test whether the fields support analysis | Build and maintain connectors, API ingestion, CDC, batch or streaming pipelines | Who owns a new source from access request through production? |
| Models and transformations | Build reusable fact, dimension, intermediate, or data-product models | May build transformations too; often ensures pipeline and warehouse support | Which models or schemas will I be responsible for? |
| Warehouse/platform | Work within platform constraints and propose improvements | Own compute, storage, orchestration, infrastructure, availability, and scaling | Who owns warehouse configuration, upgrades, and service reliability? |
| Tests and trust | Define model-level tests, documentation, lineage, metric consistency, and user-facing quality | Build pipeline checks, freshness/volume monitoring, recovery, and platform safeguards | Which tests block a release, and who responds when they fail? |
| Stakeholders | Regularly gather requirements and explain data products to business users | Partner with source teams, platform users, and analytics teams on infrastructure needs | How much direct stakeholder work is part of a normal week? |
| Operations | May own model freshness and production data products; exact on-call varies | May operate ingestion and platform services, including pipeline recovery and on-call | What are the service-level targets, rotation, and incident escalation? |
The verbs can help, but read their objects. “Model,” “define,” “document,” “test,” “publish,” and “enable self-service” may point to curated datasets and business semantics. “Ingest,” “orchestrate,” “provision,” “scale,” “optimize,” and “operate” may point to source pipelines and platform capabilities. Yet both lists can appear in one role, and “own” can refer to technical delivery, stakeholder coordination, or service operations. Check which systems, code, and outcomes belong to the role.
Also separate the names of tools from the work itself. SQL appears across analytics models and data pipelines. Python, Java, or Scala may be used in ingestion, orchestration, and transformations. dbt is common in analytics development, but its presence does not settle the team boundary. Airflow or another orchestrator does not prove that a job is all infrastructure. Look for the codebase, users, production contract, and person expected to resolve failures.
Employer examples reveal different team boundaries
GitLab’s public Analytics Engineer job-family guide places the role between business teams, Data Analytics, and Data Engineering. Its described responsibilities include gathering business requirements, designing dimensional models, writing dbt code, maintaining a data catalog, documenting work, and reviewing model changes. At intermediate level, the guide assigns ownership of major sections of the company’s dimensional model. This is GitLab’s documented role model, not a rule that every Analytics Engineer owns a warehouse model or uses dbt.
GitLab’s Data Engineer guide describes a different center of gravity: data movement and orchestration, maintaining the data platform and warehouse, building pipelines from internal and SaaS sources, writing production code, and planning platform expansion. The same guide also lists analytical warehouses, SQL, ETL/ELT, dbt, and Kimball modeling in its requirements. That overlap is useful evidence: tool names and techniques do not form a clean line between job families.
GitLab’s Analytics Engineering team handbook further shows that duties can be shared. The team says it integrates and conforms data from many sources and encodes business logic in dbt models. It also works with the Data Platform team on the central warehouse and with governance teams on data quality. Even in an organization with named functions, one outcome may involve several owners.
A dbt Labs guide describes analytics engineering as a practice focused on turning data into tested, documented and usable models, while data engineering may focus more on the platform, integrations, orchestration, and performance that enable those transformations. The guide also notes that data engineers can build pipelines and that less mature teams may combine responsibilities. It is a product vendor’s conceptual framing, not neutral labor-market research; use it to generate questions, then rely on the employer’s posting and team answers.
| First-party example checked October 13, 2026 | Responsibilities the source describes | What it supports—and what it does not |
|---|---|---|
| GitLab Analytics Engineer job-family guide | Business requirements, dimensional models, dbt code, documentation, catalogs, and model review | A company-specific model/semantics emphasis; not a universal tool requirement |
| GitLab Data Engineer job-family guide | Ingestion and orchestration, platform/warehouse, production code, systems expansion, SQL and modeling | A platform/data-movement emphasis that still overlaps with modeling |
| GitLab Analytics Engineering team handbook | Source integration, business logic in dbt, and shared platform/governance work | Team ownership can span functions and layers |
| dbt Labs conceptual guide | Curated analytics models alongside platform and integration capabilities | A vendor’s framing of the practice, not an independent survey of all employers |
These sources describe published job families and team responsibilities. They do not prove how often a specific person writes SQL, handles incidents, meets stakeholders, or builds infrastructure. If the split matters, ask for one recent project and trace the owners from source connection to a metric someone uses.
Ask about the failure path, not only the build path
A role’s operational responsibilities can change its day-to-day work. Ask who responds when a source API changes, an orchestrated pipeline fails, warehouse costs spike, a model test detects a business-definition problem, or a dashboard shows stale data. One issue may cross several teams. Clarify who diagnoses it, who communicates with the data consumer, who changes the code, and who is accountable for restoring trust.
For both roles, ask whether the team has freshness, completeness, correctness, or availability targets; what monitoring and lineage tools it uses; how changes are reviewed and deployed; and what the on-call or support rotation requires. “Production ownership” could mean keeping an Airflow service available, maintaining model freshness, responding to failed transformations, or partnering with a source owner. Ask which applies and how frequently it interrupts planned work.
For Analytics Engineer roles, ask who defines business logic and how disagreements about metric meaning are resolved. Ask whether the role owns tested models through deployment and monitoring, how much time goes to stakeholder discovery, and whether analysts can contribute to the same codebase. Learn whether the models serve one business function or support shared, company-wide definitions.
For Data Engineer roles, ask which sources and platform components you would own, whether the team emphasizes batch, streaming, APIs, warehouse operations, or data products, and where analytics transformations fit. Ask what level of modeling is expected, how pipeline failures are handled, and whether performance, reliability, or cost are measured for a system you maintain.
Choose the work you want to repeat
An Analytics Engineer search may fit if you enjoy turning business questions into well-defined, tested data models and helping teams use trusted datasets. Look for requirements gathering, dimensional or semantic modeling, SQL/dbt or similar transformation work, documentation, code review, and direct model ownership. Confirm the platform and operational expectations rather than assuming the work ends when a model is built.
A Data Engineer search may fit if you enjoy making data arrive, move, and remain available: source integration, pipeline design, orchestration, warehouse or lakehouse systems, reliability, performance, and scale. Look for specific sources, infrastructure, processing patterns, and service responsibilities. Confirm how much modeling, business definition, and end-user work belongs to the role.
Consider two fictional candidates. Mei likes SQL, and she also likes learning why Finance and Product define a metric differently. She wants to turn that ambiguity into a model with clear logic and tests. She compares Analytics Engineer postings for business discovery, model review, and production ownership, then asks whether stakeholder teams or analytics engineers define final metric rules.
Andre prefers connecting new source systems, improving pipeline reliability, and making data available at scale. He compares Data Engineer postings for ingestion, orchestration, platform tools, and on-call, then asks where transformation models are maintained. He is still interested in Analytics Engineer openings that own production pipelines if they also include the business-model work he wants. Neither candidate chooses by acronym alone.
The titles can be interchangeable at one company and distinct at another. Some organizations use Analytics Engineer for a role that blends modeling, data products, platform work, and operations; others use Data Engineer for end-to-end warehouse and transformation ownership. Treat the posting as a description of a specific team’s contract, not a guarantee about every job with that title.
Screen postings by layer and ownership
Before applying, highlight each named data layer, system, and user. For every responsibility, note whether you would build, maintain, review, operate, advise, or only collaborate. Then compare those signals with the work you want to do most often. A job that says “data models” may focus on implementation, business definition, or governance; a job that says “pipelines” may mean source integrations, transformations, platform services, or all three.
Browse recent roles on LandOffer.ai to create a shortlist. Verify the company’s actual job description, location, level, required stack, stakeholder expectations, data ownership, and operational rotation before applying.
Sources and Further Reading
- GitLab Analytics Engineering job-family guide — GitLab’s model responsibilities, dbt work, business requirements, and code ownership.
- GitLab Data Engineering job-family guide — GitLab’s platform, ingestion, orchestration, warehouse, and SQL/modeling expectations.
- GitLab Analytics Engineering team handbook — first-party example of source integration, business logic, and shared team responsibilities.
- dbt Labs: Analytics engineering and data engineering — the vendor’s explanation of how the practice and platform responsibilities can divide or overlap.
- dbt documentation: What is dbt? — product documentation for modular analytics code and transformation workflows.
Employer and vendor sources were checked October 13, 2026. They describe specific team models and tools, not universal job definitions or observed employee time allocation. Requirements and openings can change.