LandOffer
Engineering Practice
Unit, Integration, or End-to-End Test? Put the Check at the Right Layer
Place checks where they can expose the specific failure. A completed checkout map and executed local SQLite example show what isolated tests miss, which repeated checks to move and which user journeys remain necessary.
Put a check at the smallest test layer that can expose the failure you care about. Use a unit test for an isolated rule, an integration test that crosses the relevant component boundary, and an end-to-end test when the risk depends on the assembled user journey. Keep broader checks where they add evidence that a smaller check cannot provide.
The goal is useful confidence and diagnosable failures, not a prescribed percentage of each test type. This LandOffer.ai guide uses one fictional checkout flow to map failures to layers, then demonstrates a real local defect that green calculation tests miss. The executed example uses synthetic inputs and an in-memory SQLite database. No browser, payment provider, account or actual transaction was involved.
Name the failure before naming the test
“Test checkout” is too broad to select a useful boundary. “Quantity zero reaches the total calculator” and “the saved total is expressed in the wrong unit” describe different failure modes. A test of the first can pass while the second remains broken.
Google's April 2015 testing article explains the diagnostic and feedback problems of a strategy dominated by end-to-end tests. It distinguishes isolated-unit checks from component interactions and whole-product scenarios. Treat its pyramid as a design aid, not a requirement to reproduce an exact historical ratio in every service.
Define the boundaries your team uses. Here, a unit check calls a calculation function without a database or network. An integration check passes its result through the repository adapter into actual SQLite and reads it back. An end-to-end check would start at the checkout interface and inspect the resulting confirmation across the configured application path. None of these names alone says whether an external provider is real or substituted.
A route-level test with a fake repository can cover HTTP handling without testing storage. A browser test with every backend response stubbed can cover interface behavior without proving the backend is connected. Both can be valuable; label the boundary and substitutions instead of upgrading the confidence claim because the test opens a browser.
Map one checkout flow to its actual risks
Everything about PaperHarbor, its people and its original suite below is authored fiction. It sells printed workshop packs. Its simplified flow is: checkout interface → order handler → total calculator → repository → controlled payment response → confirmation. This is a teaching architecture, not a payment implementation or advice about handling actual customer funds.
The local calculator uses integer minor units. One pack costs 1,875 units, quantity is one and shipping is 275 units, giving a total of 2,150. The fixture has no tax, discount, currency conversion or payment authorization logic. Those omissions are scope limits, not suggestions that a real checkout can omit them.
QA engineer Inez and developer Omar complete this layer map before rearranging the fictional suite:
| Failure to expose | Chosen check and real boundary | Why this layer earns its place | Remaining gap |
|---|---|---|---|
| Quantity zero or negative amounts accepted | Unit: calculator rejects invalid inputs | Directly exercises the stated rule with a precise failure | Does not show that interface validation or the handler calls this rule |
| Multiplication or shipping addition wrong | Unit: explicit expected totals across supplied cases | Expected amounts are readable without navigating checkout | Does not verify storage or a provider payload |
| Correct total stored in major rather than minor units | Integration: calculator result through adapter into actual test database, then readback | Crosses the conversion boundary where the defect can occur | SQLite result does not establish behavior in another database engine |
| Handler fails to invoke the repository | Focused handler/component check with controlled dependencies | Verifies the call path without making every arithmetic case a browser journey | Substituted storage needs its own integration coverage |
| Checkout button never submits the form | Interface or bounded end-to-end journey from user action to confirmation | Requires rendered interaction and connected application behavior | Local Python checks do not execute it |
| Confirmation appears after a controlled decline | Bounded journey with an explicitly controlled response | Checks that the visible result reflects the application's outcome | Does not establish live provider behavior or actual settlement |
The map is a completed placement decision, not evidence that every row has been implemented. Only the pure calculator and SQLite-adapter portions are executed for this article. The other rows state what the fictional team must retain or add, with gaps visible.
Use the same exercise when a real incident reveals a missing assertion. Ask which component can be wrong independently of the others. If the bug lies in persistence mapping, mocking the repository at every layer removes the interaction you need to observe. Add a check across the missing boundary instead of adding more inputs to a calculation that already passes.
Read a failure that isolated checks cannot see
The companion fixture ran locally on October 27, 2026 with Python 3.12.14 and SQLite 3.54.1. Its calculator multiplies unit amount by quantity, adds shipping and rejects the supplied invalid inputs. Four valid inputs and three invalid inputs satisfy their unit expectations.
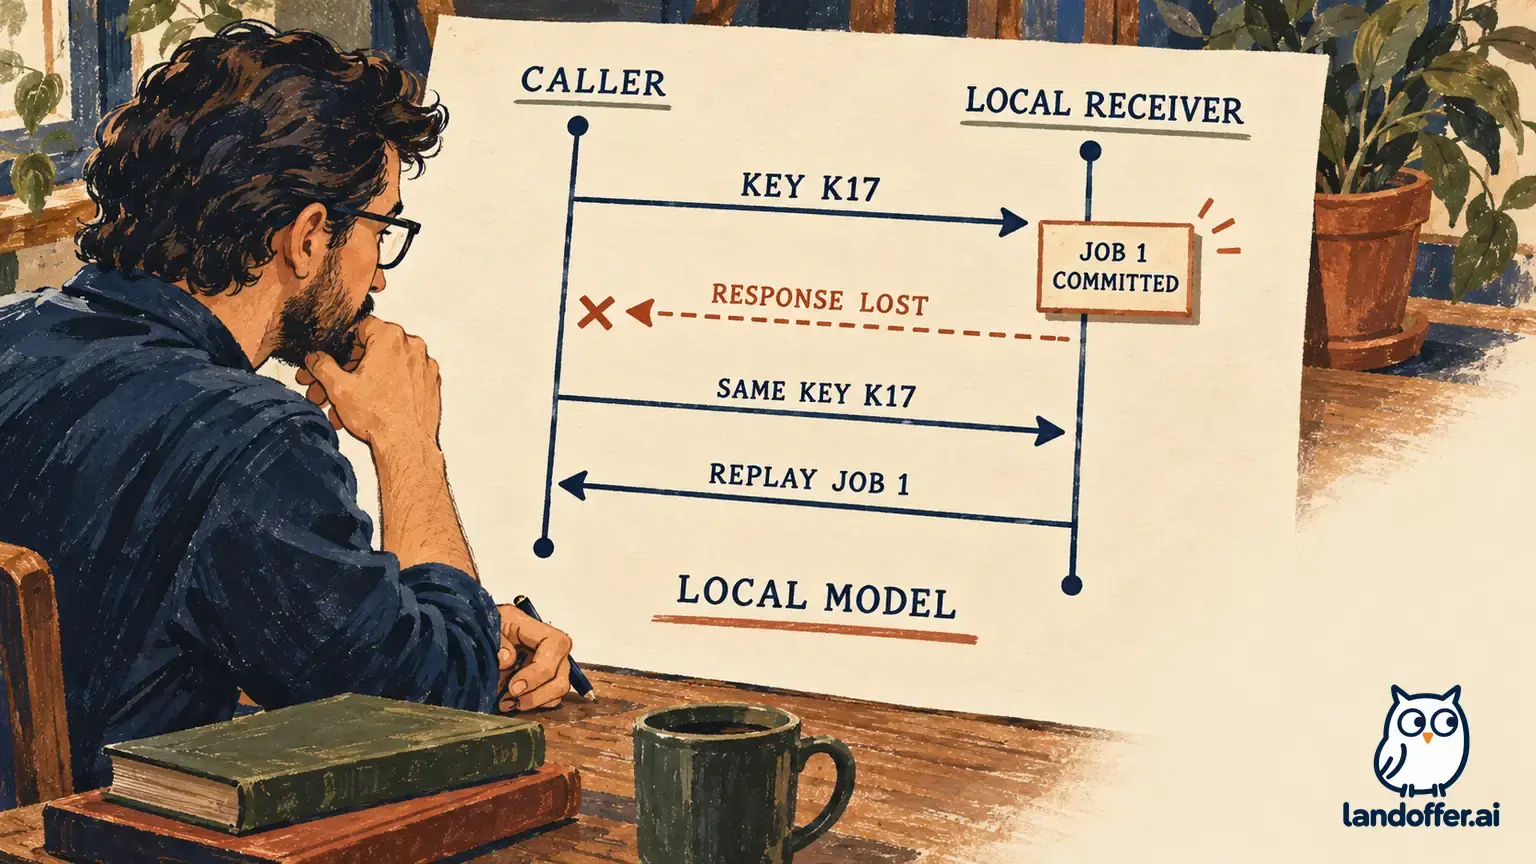
The intentionally faulty repository adapter divides the correct amount by 100 before inserting it into a column named total_minor. The 2,150-unit calculation is still correct. The stored value becomes 21.5, with SQLite reporting storage class real. A test that mocks the adapter or asserts only the returned calculation misses that change in meaning.
SQLite's datatype documentation explains that ordinary tables use type affinity rather than enforcing a single rigid storage type in every column; it separately documents the availability of STRICT tables. This fixture deliberately uses an ordinary table. A declaration containing INTEGER therefore does not, by itself, establish the intended amount invariant in this example.
The integration expectation names both value and storage class: read back 2150 as integer. That gives the developer a specific conversion boundary to inspect when the unit calculation remains correct. The faulty mapping fails that expectation. The correction removes the division in the adapter and leaves the calculation unchanged. Four readback cases then store their expected integer totals in the same test connection. They do not test durability across a restart, transaction recovery or another database engine. This is a local demonstration of a boundary failure, not a discovered production payment defect.
| Evidence | Before adapter correction | After adapter correction |
|---|---|---|
| Four valid calculator cases | Pass: 2,150; 448; 0; 15 | Same calculator and expectations |
| Three invalid calculator cases | Pass: expected rejection | Same input checks |
| Primary persistence example | Expected 2,150 integer; observed 21.5 real | Observed 2,150 integer |
| Four persistence readbacks | Initial defect demonstrated with the primary case; other faulty-adapter cases not claimed | All four supplied cases match expected totals and integer storage |
| Browser journey | Not run | Not run |
| Provider or actual charge | Not contacted | Not contacted |
The harness contains thirteen assertions, including assertions that the deliberately broken result fails the product expectation. A successful harness run records that failure faithfully; it does not mean the initial application code passed its regression check. Preserve the expected and observed values when reporting a red-to-green example.
Adjust repeated checks without deleting their purpose
PaperHarbor's fictional review begins with three browser journeys differing only in arithmetic inputs. Each navigates to checkout, enters a quantity, submits and inspects confirmation. The team also has several calculation tests but no database readback check. This is an authored suite inventory, not measured browser runtime or flakiness data.
Inez records a bounded adjustment. Move repeated multiplication and shipping expectations into the focused calculation cases. Add the adapter/database readback checks that expose the unit-conversion defect. Keep one connected success journey and one controlled-decline journey because button wiring and confirmation behavior cannot be established by the calculator fixture.
The adjusted record names what each retained journey still needs to assert: the user can submit through the rendered control; the application follows the expected path; and the confirmation matches the controlled outcome. It does not retain the journey merely because “some E2E tests are required,” or remove it merely because smaller tests are green.
Omar marks the local calculation and storage checks as executed, with the faulty mapping demonstrated and corrected. Inez owns the connected success and decline journeys, which remain pending implementation and execution in the fictional review. Their controlled response setup must be reviewed before either can count as evidence. No existing repository tests were deleted, and no release approval follows from the new local checks. The completed deliverable is a reasoned coverage adjustment with an honest remaining gap.
Before removing an actual repeated test, compare its assertions and setup. A journey that looks numerically repetitive might also exercise a distinct shipping option, authorization boundary or failure presentation. Move only the duplicated obligation; retain or replace its unique evidence. Accept the adjustment only after accounting for each removed check's distinct failure risk.
Keep substitutes, data and diagnosis visible
Playwright's current best-practice guidance recommends checking user-visible behavior, isolating tests and controlling dependencies that you do not own. It also favors user-facing locators and assertions that wait for expected interface state. Those practices can make a browser check more informative, but they do not turn a controlled provider response into proof that a real payment system works.
For PaperHarbor, a controlled decline means the test supplies a known unsuccessful response. It should inspect how the application handles that outcome without charging a card. Verification of an external integration would require an authorized provider test environment and its own documented scope. This article performs neither that test nor a contract-testing exercise.
Control the database state too. The fixture creates a new in-memory database for the faulty example and another for the corrected cases, then closes them. It neither reads a developer's existing orders nor modifies a shared test environment. In a real suite, setup and cleanup must preserve that isolation through the relevant boundaries.
When a broad journey fails, keep the failure evidence before rerunning it. Check whether the application behavior, test data, environment or assertion is wrong. A focused integration test may help isolate the boundary, but changing layers is not permission to ignore a genuine end-user failure. Conversely, a permanently mocked boundary can stay green while the real interaction breaks.
Do not claim a speed improvement without comparable measurements. This article records cases and results, not durations or a reduction in flakiness. Smaller scope is a design choice aimed at clearer feedback; the actual maintenance cost and reliability of a suite still need observation in its environment.
Finish with an owned coverage decision
For each important failure mode, record the narrowest meaningful check, what remains real, what is substituted and what a pass cannot establish. Assign an owner to the gap rather than hiding it behind the number of passing tests. Keep higher-layer coverage for risks that require the assembled interaction.
The local PaperHarbor result supports one limited conclusion: isolated calculation checks can pass while a real storage interaction is wrong, and a focused boundary check can expose that specific error. It says nothing about the correctness of an unexecuted browser journey or live payment processing.
For your next test review, complete a map like this one and attach one observed failure with its corrected result. Bring any proposed removal of repeated checks to the owner of the remaining user-level risk. LandOffer.ai publishes this as practical engineering reading; take the completed map, observed failure and still-unexecuted journeys to the reviewer who owns coverage and release decisions.
Sources and Further Reading
- Google Testing Blog: Just Say No to More End-to-End Tests, Mike Wacker, April 22, 2015; body checked October 27, 2026 through its public mobile rendering after the initial fetch timed out. Historical method, not a current mandatory ratio.
- Playwright: Best Practices, current body checked October 27, 2026. No Playwright/browser tests executed here.
- SQLite: Datatypes In SQLite, current body checked October 27, 2026. Local observations concern ordinary SQLite tables, not every database engine.