LandOffer
Engineering Practice
Test with Realistic Data Without Copying Customer Records into Development
Preserve useful formats and relationships with independently authored test records. A reproducible booking fixture exposes tenant and interval errors while a completed trade-off record keeps privacy and coverage limits visible.
Build realistic test data from the formats, relationships and failure conditions your application must handle, rather than copying customer rows into development. Start with explicit constraints and named boundary cases, generate independent fictional records, then check both the data and the behavior it is meant to exercise. Values that look plausible can still omit the relationship or exact boundary that triggers a failure.
Keep the evidence boundary clear. A generated fixture can expose a missing tenant filter without proving that an actual deployed system protects customer information. This LandOffer.ai guide provides a completed dataset design and a checked local example. No customer records, production statistics, account exports or model trained on customer data were used.
Decide which characteristics the test actually needs
Microsoft's Azure testing guidance recommends synthetic data with relevant production characteristics and keeping test assets aligned with changing schemas and scenarios. That is a reason to define useful structure, not permission to export real records because they are convenient.
Identify the decision you need the test to support. A date-range filter needs records before, inside and exactly on its boundaries. A tenant-scoped lookup needs identical local identifiers in different tenants. A display field might need missing values, Unicode and its stated length limit. For these checks, use independently invented values rather than a customer's name, note, schedule or address.
Use approved schema definitions, documented requirements and appropriately reviewed aggregate descriptions where available. Record which characteristics remain assumptions. Avoid presenting a made-up distribution as observed customer behavior. If an authorized aggregate is used, its provenance and disclosure constraints still need review; this example uses none.
Choose whether a case belongs in the valid dataset or a separate rejection set. A broken foreign key deliberately tests input rejection, but mixing it unnoticed into a nominally valid fixture can make every downstream test ambiguous. Give each invalid case its own expected error and owner so a rejected input is not confused with a broken test setup.
Complete a dataset contract before generating rows
The LanternSchedule equipment-booking application and its requirements below are entirely fictional. QA engineer Anika needs to review tenant isolation and date-window filtering. The application model has resources identified by the pair (tenant, resource), with bookings referring to that pair.
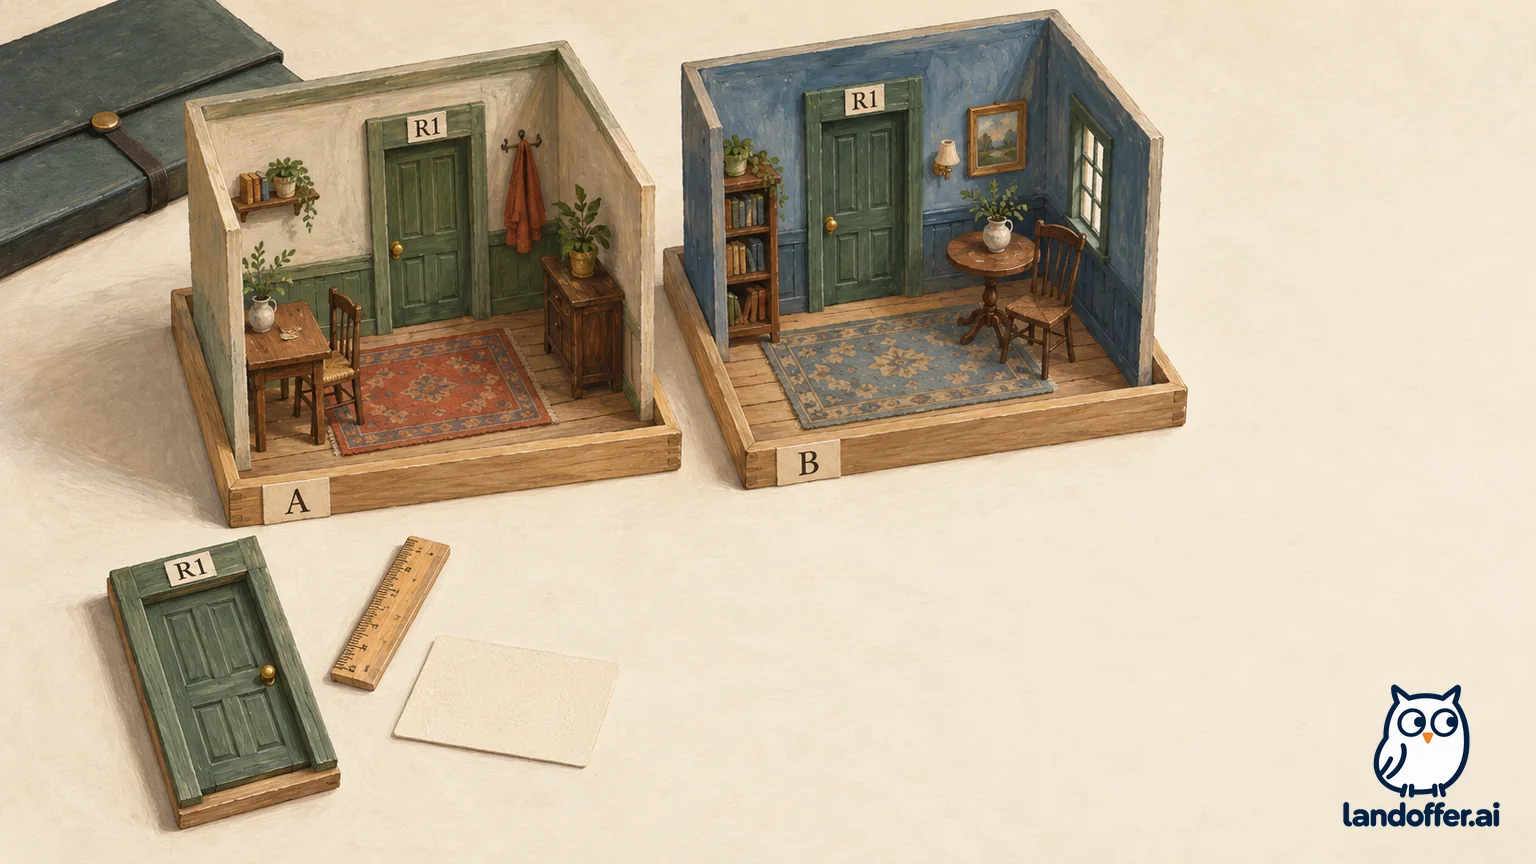
Anika's completed contract creates two tenants, A and B, and three resources: A/R1, A/R2 and B/R1. Reusing R1 is intentional. Resource identifiers are unique only within a tenant, so a test dataset that makes them globally unique would hide an important failure mode.
| Characteristic or risk | Completed authored design | Evidence or remaining limit |
|---|---|---|
| Relationships | Each valid booking references one of the three tenant/resource pairs | Validate the pair, not resource name alone |
| Time representation | Timezone-aware ISO timestamps with UTC offsets | This fixture does not cover daylight-saving transitions or mixed offsets |
| Interval convention | Start is included; end is excluded; end must be later than start | Adjacent bookings must not be treated as overlapping |
| Status | Active and cancelled examples | Cancelled entries are excluded from the queried active set |
| Optional content | Every note is null because free-text notes are irrelevant to these checks | No real notes or synthetic imitations of customer narratives needed |
| Label format | A Unicode label, ordinary labels and one exactly 64 Python-code-point label | Bytes and user-perceived character counts need different tests |
| Positive population | Five explicitly authored boundary records plus 20 generated supplements | Twenty extra records are not a load test or a measured customer distribution |
| Negative population | Unknown resource, zero-duration interval and 65-code-point label, stored separately | Each mutation has one named expected validation error |
| Repeatability | Generator version, Python version, seed 271026 and output hash retained | Repeatability does not establish realism, completeness or confidentiality |
The first five records carry the actual test argument. The supplements provide repeatable variation in duration, status and dates. Their values come from authored rules, not a fitted population model. Generating more of those rows cannot substitute for an omitted boundary.
The fixture deliberately contains no contact addresses, credentials, account tokens or real names. Labels such as “Other workspace” identify the teaching case, not an actual person. Removing a field the test does not need is simpler than inventing a realistic identity and then trying to prove it cannot contact or identify someone.
Inspect the completed boundary records and their results
The generator and Python filtering checks ran locally on October 27, 2026 with Python 3.12.14. The main JSON contains 25 valid bookings and three resources. Three invalid mutations are retained separately with their expected errors. There is no database, API, browser or actual application execution in these checks.
All five boundary bookings use invented dates on October 27, 2026. Their labels and times are authored test values, not observations of anyone's schedule.
| Booking | Tenant/resource | UTC interval | Status | Purpose |
|---|---|---|---|---|
| B001 | A/R1 | 10:00–11:00 | Active | Ends exactly when the second query starts; Unicode label |
| B002 | A/R1 | 11:00–12:00 | Active | Expected active result for the 11:00–12:00 query |
| B003 | A/R1 | 12:00–13:00 | Cancelled | At the upper boundary and cancelled; not an active result |
| B004 | B/R1 | 10:30–11:30 | Active | Same local resource identifier in the other tenant |
| B005 | A/R2 | 10:00–11:00 | Active | Different resource; exactly 64-code-point label |
For tenant A, resource R1 and window 10:00–12:00, the expected result is B001 and B002. A deliberately faulty filter that checks only resource R1 also returns B004. The fixture therefore exposes an omitted tenant condition without including another customer's information. This is a local illustrative failure, not a reported data leak.
For the 11:00–12:00 window, the expected result is B002 only. Another deliberately faulty filter uses booking_end >= window_start and incorrectly includes B001, whose booking ends at 11:00. The corrected condition uses a strict greater-than comparison for that edge, alongside booking_start < window_end.
The saved result records both incorrect results alongside the corrected expectations. Its 41 assertions cover declared counts, unique booking IDs, valid relationships and intervals, selected label cases, repeat generation, negative-case errors and these filtering expectations. A successful harness run preserves the fact that the injected filters failed their intended behavior.
The output hash is saved with the fixture so a reviewer can compare the exact generated file. Python's random documentation explains reproducibility and cautions that algorithms can change across versions. Retain the generated artifact and runtime information as well as the seed. The pseudorandom generator is not used to create secrets or make a privacy guarantee.
Trade realism against sensitivity explicitly
A dataset can be structurally useful while intentionally unlike production in other respects. Anika completes this decision record rather than claiming that all synthetic rows are representative or safe by definition.
| Possible source or characteristic | Decision for this task | Benefit and unresolved trade-off |
|---|---|---|
| Customer booking export | Do not obtain or copy it | Independent boundary records cover the named failures; historical patterns remain unrepresented |
| Resource relationships | Generate composite identifiers and explicit references | Preserves the tenant-scoping obligation without actual resource identities |
| Actual customer free text | Omit; notes remain null | Avoids unnecessary narrative content; note rendering and search require another fixture |
| Exact real timestamps | Invent times and explicit adjacent intervals | Makes expected results easy to review; geographic and daylight-saving cases remain open |
| Customer frequency distribution | Do not claim one | Chosen proportions emphasize failures, not market or workload statistics |
| Rare real customer case | Reconstruct the minimum failure condition from an approved description, if needed | Any description containing identifying details still requires its own handling review |
| Larger generated population | Keep separate from performance claims | Functional checks pass; throughput, contention and realistic load remain untested |
Changing names in a customer export would not satisfy this record's no-copy design. Indirect identifiers, detailed timelines and free text can retain identifying information. The UK ICO's anonymisation guidance emphasizes context and identifiability beyond obvious names; its guidance also says masking alone is not an effective anonymisation technique. The site currently marks this guidance as under review following UK legislative changes. That is a scoped source caution, not a legal conclusion about a reader's dataset.
Rule-authored test fixtures are also different from a synthetic model trained on real records. A learned generator has source-data, model and disclosure questions that do not disappear when its output is labeled synthetic. This article neither trains such a model nor certifies anonymisation, differential privacy or compliance with any jurisdiction's requirements.
Keep generated data out of real side effects
If a test application can send messages or change connected systems, fictional record content alone does not prevent those actions. Data design and environment isolation are separate controls. For a real test environment, use the team's authorized configuration for outbound services, credentials and access boundaries rather than relying on labels saying “test.”
The executed script here contains no network operation, no message-sending function and no account credential. It writes only the generated article dataset and its result record. That scope is inspectable in the saved code; it does not demonstrate isolation of an actual deployment or establish that some other tool cannot act on the file later.
Review where fixtures travel: version control, build artifacts, logs, screenshots and issue attachments can all carry data. Use approved storage and retention rules for the actual project. Avoid pasting a real incident's raw payload into a synthetic fixture merely to help the next developer reproduce it.
If a failure cannot be represented adequately, record the missing property and take it to the responsible data and engineering owners. That is a reason to design an approved investigation, not an automatic exception allowing a production dump. The fixture's success supports only its named checks and cannot authorize access to real records.
Accept the evidence and keep the gaps visible
Anika's completed review accepts the fixture for the two local filter conditions and its stated schema checks. It retains the missing-tenant and inclusive-end failures as regression examples. Two calls to the generator reproduce the same bytes within the inspected runtime; that comparison does not guarantee identical output after a runtime or generator change, and the three deliberately invalid mutations return their expected errors.
The review does not accept the fixture as a complete booking-system test. Actual application enforcement, concurrent bookings, authorization, daylight-saving behavior, notes, mixed offsets and load remain outside the executed scope. Anika records the missing data cases for the next test-plan review, while the application owner must define enforcement and concurrency checks. Their implementation and results remain unverified.
For your next data-dependent check, complete a constraint contract, include a small set of named boundary records and attach expected versus observed results. Ask the reviewer which production characteristic remains unsupported and whether the test truly needs sensitive information to address it. LandOffer.ai publishes this as practical engineering reading; take the completed contract, named boundary records and unverified properties to the reviewer responsible for the next test decision. Any request for real data needs its own authorized review.
Sources and Further Reading
- Microsoft Azure Well-Architected: Architecture strategies for testing, updated July 30, 2026; relevant representative-data sections checked October 27, 2026.
- Python 3.12: random, notes on reproducibility, documentation updated October 26, 2026; local execution used Python 3.12.14, not every documented maintenance version.
- ICO: How do we ensure anonymisation is effective?, current body checked October 27, 2026; marked under review. No legal or privacy certification claimed.