LandOffer
Job search
ML Infrastructure Jobs vs. Model-Building Roles: Search for the Work You Actually Want
Compare ML infrastructure and model-building jobs by platform ownership, model experimentation, production operations, and the work each posting expects.
ML infrastructure and model-building roles can both involve GPUs, PyTorch, training runs, and production systems. Choose between them by identifying the artifact and decisions you will own: reusable foundations that let teams train, evaluate, and serve models, or methods and experiments intended to change model behavior or quality. The boundary is real but porous. One current Anthropic infrastructure role includes research workflows and moving them into production; its pretraining research-engineering role also includes training infrastructure and tooling. These are examples from specific openings checked October 13, 2026, not a labor-market census.
LandOffer publishes this guide. You can browse recent roles on LandOffer, then confirm responsibilities and eligibility on the employer's own posting. A search title can suggest where to look; the responsibility verbs and deliverables should decide whether a vacancy belongs on your shortlist.
Start with the artifact you will own
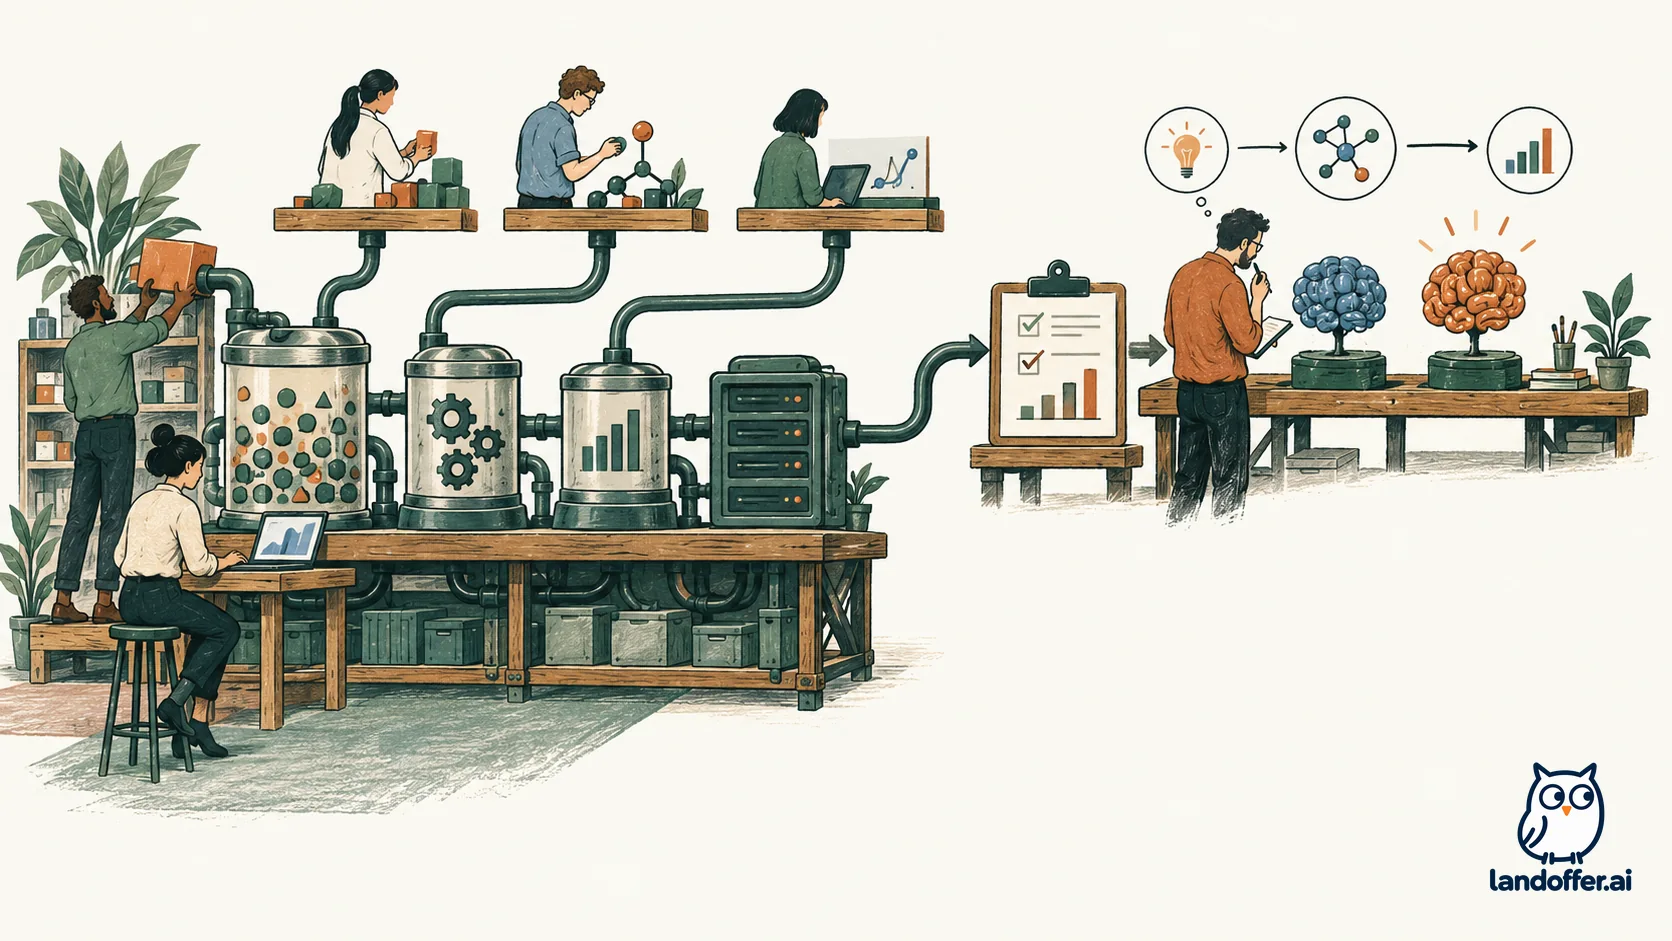
A useful distinction is whether the primary deliverable serves many model efforts or advances a particular model effort. Infrastructure work often creates reusable data pipelines, training orchestration, evaluation frameworks, inference services, monitoring, or reliability improvements. The results may be measured in throughput, reproducibility, cost, latency, availability, or the number and quality of experiments a team can run. Model-building work more directly develops or selects architectures, training methods, post-training recipes, data strategies, or evaluation approaches intended to affect model capability or behavior.
That distinction describes a center of gravity, not a strict boundary. Infrastructure choices shape what researchers can test and how reliably they interpret results. Model builders may maintain their own training and evaluation pipelines. A role can span both; identify which decisions and outcomes you will lead.
The lifecycle offers a map. Data ingestion and validation feed training. Training produces a checkpoint or other model artifact. Evaluation estimates how it performs against intended tasks and constraints. Serving makes it available to users or internal systems. Monitoring and incident response show what happens after launch. An infrastructure engineer might own the reusable pipeline, job scheduler, serving platform, or correctness checks across this lifecycle. A model builder might decide which training change to test, interpret results, and determine whether an improvement is worth implementing. A research engineer may own the glue between these steps, including both scientific implementation and the platform pieces needed to run experiments.
When you read a posting, ask: “What will be different because this person did the job?” If the answer is that a team can train or evaluate more reliably, at lower cost, or with less operational friction, the center of gravity may be infrastructure. If the answer is that a model is trained differently, behaves better on a target, or has a more convincing measured result, model-building may be central. If both answers fit, inspect which responsibility is explicit, which is supporting work, and how the team will evaluate success.
Compare current postings by responsibility
Three Anthropic descriptions make the overlap concrete. The Machine Learning Infrastructure Engineer, Safeguards Research posting describes research data, training, evaluation, and scoring infrastructure; correctness checks; moving selected workflows into production; and improving throughput, cost, and reliability in partnership with researchers. The output is infrastructure, but it is close to safeguards research and can affect the pace and quality of that work.
The Research Engineer, Production Model Post-Training posting centers methods and recipes to improve production model quality. It also names fine-tuning and evaluation pipelines, performance measures, production implementation, and operational reliability. This is model-building with meaningful systems responsibilities. The Research Engineer, Pretraining posting combines architecture and algorithm work, experiments, data processing, optimizer work, training-infrastructure optimization, and developer tools. It is a direct example of a role where forcing a clean platform-versus-model label would obscure the job.
| Posting signal | Infrastructure-centered example | Model-building-centered example | What to verify in your target role |
|---|---|---|---|
| Main deliverable | Research data, training, evaluation, or scoring systems; correctness and reliable production workflows | Methods and recipes intended to improve production model quality | Which system, model, method, or workflow will the hire own? |
| Decisions | How workflows run, scale, fail safely, and become maintainable | Which model changes or training approaches to test and whether results justify adoption | Who chooses the experiment, interprets its result, and approves the next step? |
| Measures | Throughput, cost, reliability, correctness, reproducibility | Evaluation outcomes, model quality, capability, or behavior on named tasks | Are measures stated, and do they apply to the platform or the model? |
| Technical overlap | Research tooling, evaluation, production transitions, collaboration with scientists | Fine-tuning and evaluation pipelines, implementation, operational reliability | Which work is central and which supports the central outcome? |
| Example limitation | One safeguards team and its stated responsibilities | One post-training or pretraining team and its role-specific scope | Do not generalize requirements, tools, or team structure from one vacancy. |
Treat the table as a reading aid, not a taxonomy supplied by the employer. The job descriptions provide the evidence; “centered” is an editorial interpretation of their stated deliverables. The pretraining posting combines architecture, algorithms, data, infrastructure, and tooling, so it belongs in an overlap category for a candidate who wants either deep systems work or model-focused experimentation. Put the role on your shortlist when its central responsibilities match both the work you want and the evidence you can substantiate.
Distinguish infrastructure for models from model work
Some words are weak signals on their own. “GPU,” “distributed training,” “evaluation,” “PyTorch,” and “production” can appear in either track. A GPU cluster may be the platform whose scheduling and utilization you improve, or it may be the environment where you test a model method. Evaluation can mean implementing a reusable evaluation service, or designing a study that measures whether a model changed in a useful way. Production can mean reliability of the deployment platform or launching a particular model result.
Read the verbs and objects together. “Build a training platform” names a reusable system. “Develop a post-training recipe” points more directly to model methods. “Improve evaluation throughput” likely centers system performance, while “design evaluations for a new capability” points toward research decisions. “Partner with researchers to bring workflows into production” combines implementation and operational ownership. The verb, object, and expected result clarify the work.
Also look for ownership boundaries. Will you be responsible for a shared service used by multiple teams, a model's training run, an experiment portfolio, or the handoff into production? Who defines correctness? Who decides whether a metric improvement is meaningful? Who responds when a run fails or an online system degrades? These questions reveal whether “production” means occasional implementation, ongoing operations, or both. They also help distinguish a role that builds tools for research from one that is expected to shape research outcomes.
No single technology proves fit. A candidate who used Kubernetes may have operated a shared platform or merely deployed one project. Experience with PyTorch may mean building a trainer, running experiments, implementing model architectures, or debugging a workflow. Describe the decision you made, the system or experiment you owned, and how you evaluated its result. That account is more informative than matching a tool list without context.
Work two candidate decisions
Consider two fictional candidates. These examples illustrate how to use the postings; they are not candidate reports or hiring predictions.
Rina has built distributed data pipelines and training orchestration. She has investigated slow jobs, added correctness checks, improved recovery from failures, and worked with researchers who depended on the systems. She has not led model-method experiments. The Safeguards Research infrastructure role is a plausible match to investigate because the posting explicitly names data and training workflows, correctness, production transitions, throughput, cost, and reliability. Rina should choose one system, explain the constraints, identify her own design decisions, and show how researchers used it. She should not describe that platform work as direct evidence that she has improved model quality unless she can show the experiment and result too.
Dev has implemented post-training experiments, compared evaluation results, and helped move a promising change into production. He has used and modified the training pipeline, but has not owned a shared compute platform or its reliability. The Production Model Post-Training role may align more closely with his examples because the posting names methods and recipes for model quality while also requiring pipelines and implementation. He should explain the hypothesis, comparison, metric, limitations, and the production decision. If he applies to an infrastructure role, he should separately establish his ability to design and operate systems that serve other users.
A third candidate could have both sets of evidence: platform ownership and direct experiment decisions. The Pretraining posting may deserve a closer read because it names both areas. That is not a reason to claim universal flexibility; the vacancy may still prioritize particular methods, experience, or location. The candidate should map each required qualification to a specific completed project and ask the recruiter which responsibility will dominate the first project if the posting leaves the balance unclear.
A compact evidence map prevents overclaiming:
| Requirement in the posting | Evidence to select | What your example should explain |
|---|---|---|
| Reusable ML infrastructure | A service, pipeline, scheduler, data system, or evaluation platform you owned | Users, scale or constraints, reliability choices, and how you knew the system worked |
| Model methods or experiments | A training, fine-tuning, architecture, or evaluation change you tested | Question, baseline, method, result, uncertainty, and your contribution |
| Production transition | A model workflow or platform moved into a supported environment | Readiness criteria, monitoring or recovery, partners, and ongoing ownership |
| Cross-functional research work | A collaboration with researchers, product teams, or platform users | How requirements changed, what you implemented, and how decisions were made |
If an example is private or confidential, describe it at a safe level or use an approved work sample. Do not expose model weights, sensitive data, internal benchmarks, or proprietary implementation details to prove fit. A clear account of your role and decision process is more useful than an unauthorized artifact.
Screen a posting before applying
Use a short, repeatable pass. First, copy the exact title, team, level, location, and must-have requirements from the employer page. Second, underline the verbs in the responsibilities: build, operate, design, experiment, evaluate, optimize, deploy, monitor, or maintain. Third, name the object for each verb: platform, data pipeline, model, recipe, evaluation, or product workflow. Fourth, identify the measures and owners: what counts as success, who decides, and who supports the result after launch.
Then classify the role by its likely center of gravity: shared infrastructure, direct model iteration, or mixed research engineering. Keep that classification provisional until you review the qualifications and application form. A role may ask for systems depth even when it is research-adjacent, or experimental judgment even when the title says engineer. Separate required qualifications from preferred ones, and note whether the application asks for code, publications, work samples, or a technical narrative. Do not infer a degree, publication, or years-of-experience requirement from a neighboring posting.
Finally, draft a one-sentence fit statement: “I can own ___ because I have ___; I still need to clarify ___.” If the blank after “own” contains only a technology, make it more concrete. “I can own a PyTorch stack” is vague. “I built a repeatable evaluation pipeline that researchers used to compare model changes, and I can explain its failure handling and limits” names an artifact, user, and evidence. If you cannot identify relevant proof for a core responsibility, decide whether the gap is learnable, addressable with another example, or a reason to prioritize a different role.
For unclear postings, ask a focused question rather than guessing: “For the first project, is success primarily measured by platform reliability and researcher throughput, by model-quality results, or by both?” You can also ask who owns model decisions, operational incidents, and evaluation design. The answer can clarify whether the job matches the work you want each week.
Build a shortlist around work products
Search across titles such as ML infrastructure engineer, machine learning platform engineer, research engineer, training systems engineer, applied scientist, and model post-training engineer. These are search terms, not interchangeable job families. Save each opening with its deliverable, primary decisions, measures, operating duties, requirements, evidence you can show, and one unresolved question. This makes comparison possible even when employers use different titles for similar responsibilities or reuse the same title for different work.
Keep roles with genuine overlap on the list if you can make a distinct case for them. A systems-focused resume can foreground shared services, reliability, throughput, and researcher experience; a model-focused version can foreground questions, methods, evaluations, and production outcomes. Do not send a generic tools inventory to both tracks and expect the reader to infer your contribution. Use the actual posting and stay within what you can document.
To make your next step concrete, pick two current postings and complete the evidence map above before tailoring either application. Then browse recent roles on LandOffer for additional leads, and verify each role, location, requirements, and application destination on its employer page. LandOffer's listing page is a discovery starting point; it does not confirm that a particular vacancy is open or that you meet its criteria.