LandOffer
Job search
Knowledge Engineer Jobs: Check Ontologies, Knowledge Graphs, and Production Data Responsibilities
Compare actual semantic and data-platform responsibilities, inspect a supplier-scoped mapping decision, and describe ownership without inventing production authority.
Knowledge Engineer jobs can involve defining a domain’s concepts, mapping source records into a knowledge graph and maintaining the resulting data in production. Identify what you would define, map and keep reliable, then ask who approves changes to the meaning of the data. Designing a vocabulary, building an ingestion service and approving a semantic change are related responsibilities, but a posting may assign them to different people.
We checked public employer descriptions and W3C documentation on October 22, 2026. The two worked examples use fictional, nonclinical catalog data; no database, query engine or production pipeline was executed. LandOffer publishes this guide. To compare actual roles, browse recent roles on LandOffer.ai and preserve each employer’s location, requirements and work arrangement.
Identify the semantic work behind the title
Start with what the employer expects people to agree on. An ontology or semantic model can define concepts and relationships in a domain. A populated knowledge graph contains statements about particular entities. A mapping connects source fields and identifiers with that representation. A service makes the data usable by applications or other teams.
Those outputs require different evidence. A diagram can explain intended meaning without showing that records were mapped correctly. A pipeline can move records reliably while joining the wrong entities, making a downstream answer wrong even when the scheduled job reports success. A well-designed API can serve data without its author owning the vocabulary or deciding which interpretations are acceptable.
Underline what the job asks you to define, align, map, curate, validate, version or maintain. Name the actual model, mapping or service beside each responsibility. “Build AI services” is less specific than reviewing ontology changes, preserving mapping provenance or maintaining graph query behavior. A backend-heavy job can still contain substantial knowledge engineering when its services depend on those responsibilities.
For an interview, ask the team to follow one concept from a domain expert’s definition through a source record, a mapping, a graph statement and a consumer’s question. That makes the boundary between semantics and infrastructure visible. It also reveals where a disagreement is resolved rather than assuming the graph database supplies the meaning automatically.
Two current descriptions show different responsibility mixes
The Altos Labs Senior Knowledge Engineer, Ontology and Data Standards contract posting explicitly assigns review authority for canonical schema changes and ownership of curation conventions. It describes LinkML/Biolink modeling, justified mappings, provenance, validation and work with scientists and platform engineers. The missing contribution is an owner of the represented knowledge, rather than merely another service endpoint.
This is a San Francisco Bay Area contract role with senior life-science experience requirements. Its domain expectations and appointment type matter alongside software skills. Do not generalize them into a rule that every knowledge engineer needs a biology background, or assume that a contract carries the same arrangements as a permanent employee position.
The Senior Data & Knowledge Engineer posting on Encora’s career board says Coforge is hiring. It combines ingestion, extraction, retrieval indexes, metadata and knowledge graph models. Its required experience includes production data pipelines and graph technologies; RDF and ontology-related experience also appear within preferred skills. That is a broader data-and-retrieval engineering mix than ownership of a canonical ontology alone.
Its header names Colombia, while its body lists Costa Rica, Peru, Colombia and Bolivia and labels the work remote. This is not evidence of US remote availability. Preserve the listed region and clarify the applicable employing arrangement rather than treating “remote” as worldwide.
| Responsibility | Altos description | Encora/Coforge description |
|---|---|---|
| Meaning and modeling | Canonical models, ontology alignment and review authority | Entity, relationship, metadata and domain-context models |
| Data movement | Harmonization conventions and curated mappings | Ingestion, extraction, enrichment and indexing pipelines |
| Quality over time | Provenance, semantic review and curation checks | Freshness, lineage, retrieval quality and access-controlled indexes |
| Scope to verify | Senior scientific-domain authority under a contract | Regional remote data/search/graph responsibilities |
The comparison is a reading of published duties, not a ranking or a personal hiring assessment. It helps you select which artifacts to explain and which responsibilities remain outside your experience.
Read RDF, SPARQL and ontology requirements precisely
W3C’s RDF 1.1 Primer explains statements as subject–predicate–object triples and describes identifiers for resources. That gives a concrete interview question: how did you decide that two records refer to the same entity? Matching display text is not enough to explain an identity rule.
The SPARQL 1.1 Query Language specification describes matching graph patterns. A query’s result depends on the supplied graph and the pattern being evaluated. Keep an expected result for a teaching example separate from a result actually obtained from an engine, and keep both separate from a claim that the underlying business information is complete.
The OWL 2 Primer, Second Edition also distinguishes ontology semantics from a conventional database framework. In particular, an absent fact can remain unknown under the open-world assumption. An ontology description should not be presented as automatically enforcing the presence of every field in every source record.
These are named, dated references: the RDF primer is a June 24, 2014 Working Group Note; the SPARQL document is a March 21, 2013 Recommendation; the OWL primer is a December 11, 2012 Recommendation. They support the distinctions used here, without claiming that every employer uses those exact versions or an RDF-based graph.
Read the actual stack. A graph role can use a property-graph implementation, a semantic-web stack or several representations together. Learn which model you would maintain, which query language consumers use and what the team means by validation. A keyword list does not answer those architectural questions.
Worked mapping: keep supplier-scoped parts separate
The following is a fictional catalog exercise. It is not an Altos or Encora dataset, clinical ontology or production integration. Its local business rule says a part is identified by the combination of supplier and part code. The same code used by another supplier denotes a different part in this invented domain.
Three source rows are supplied:
| Source row | Supplier identifier | Part code | Recorded warehouse |
|---|---|---|---|
| R1 | S01 | 07 | W1 |
| R2 | S02 | 07 | W2 |
| R3 | S01 | 09 | Missing |
The completed small model has three classes: Part, Supplier and Warehouse. It defines suppliedBy from a part to a supplier and storedAt from a part to a warehouse. These are teaching definitions; no formal ontology reasoner or validator was run.
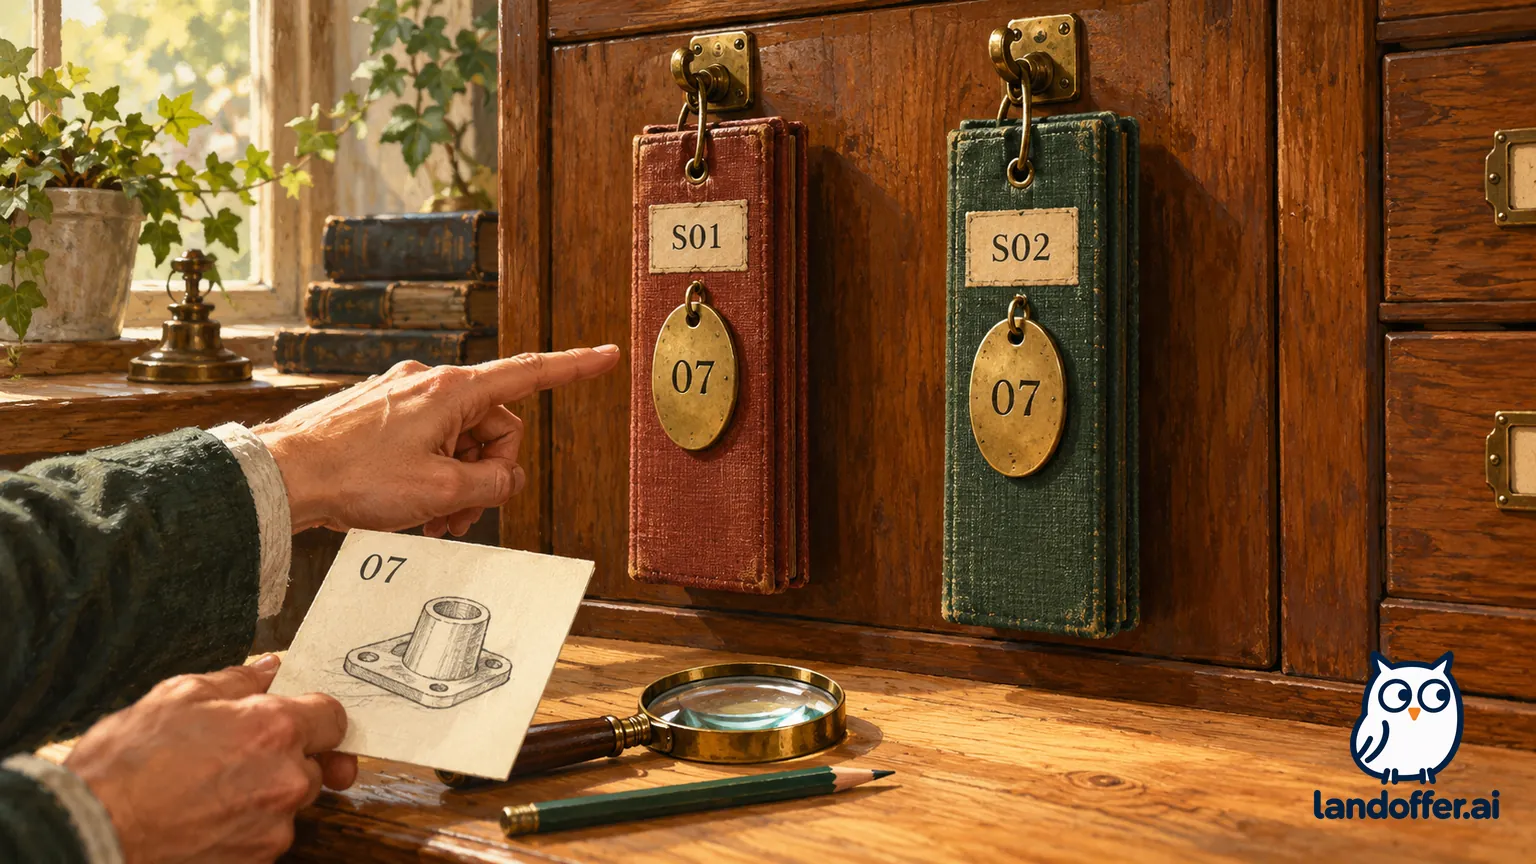
An initial mapping using part code alone would merge R1 and R2. The completed correction creates distinct identifiers part:S01-07, part:S02-07 and part:S01-09. The mapping record is:
| Row | Completed identity and relationships | Quality disposition |
|---|---|---|
| R1 | part:S01-07 suppliedBy supplier:S01; storedAt warehouse:W1 | Retain the source-row link R1 |
| R2 | part:S02-07 suppliedBy supplier:S02; storedAt warehouse:W2 | Keep separate from the other 07; retain R2 |
| R3 | part:S01-09 suppliedBy supplier:S01; no storedAt statement supplied | Record a missing-warehouse exception tied to R3 |
The competency question is: “Which parts supplied by S01 have a recorded warehouse?” Its mandatory pattern requires both suppliedBy S01 and storedAt a warehouse. By direct inspection of the stipulated facts, the expected answer is part:S01-07 with warehouse:W1. This is a manual expected-answer trace, not executed SPARQL output.
Part S02-07 is excluded because its supplier is S02. Part S01-09 does not match the mandatory warehouse relationship in the supplied graph. The missing match answers only the declared pattern against these supplied facts. It does not establish that the part is stored nowhere. Its warehouse remains unrecorded in this example; the exception record preserves that gap for review.
The completed handoff note reads: “Use supplier plus part code for identity in this catalog. Preserve R1, R2 and R3 as provenance links. Do not merge the two 07 records or invent a warehouse for R3. The current expected answer to the S01 recorded-warehouse question contains S01-07 at W1. A domain reviewer must resolve the R3 exception before any later enrichment is treated as verified.”
This asset demonstrates modeling, mapping, provenance and a consumer question together. It does not demonstrate a working graph store, production-scale entity resolution or the accuracy of a real source. A real work sample should make those additional claims only when it contains corresponding evidence.
Production responsibility includes changing meaning safely
A source system can change a code, a column’s meaning or the way it identifies an entity. The pipeline may continue to run while producing statements that no longer match the agreed model. Knowledge engineering therefore includes asking who notices the semantic change and who approves the revised interpretation.
For a prospective role, identify the release artifacts: the vocabulary version, mapping change, review record, expected-answer examples and unresolved exceptions. Ask how consumers learn that a relationship changed and whether an earlier result can be traced back to its source and model version. These are responsibilities to verify, not capabilities guaranteed by owning a particular graph product.
Also separate model review from data access and service operation. An ontologist may approve a concept while a platform engineer controls deployment. A data engineer may own ingestion while a domain reviewer resolves an ambiguous mapping. The job becomes clearer when the posting and interview identify who can make each decision.
If the role includes AI-assisted extraction or curation, ask how the team checks meaning and handles uncertain output. Syntactically valid statements can still be wrong. A plausible generated relationship needs an evidence and review path; automation does not remove the need to identify its source and limits.
Worked ownership statement: describe the mapping you delivered
Yuri is fictional. The stipulated work history contains a parts-catalog API, a supplier-scoped identifier mapping, mapping regression tests and a review note about a proposed vocabulary change. A domain reviewer approved the vocabulary; a platform team operated the graph service. These are invented teaching facts, not a real employer report.
Yuri’s first summary says, “Owned enterprise ontology and knowledge graph production.” The completed responsibility review narrows that claim:
| Fictional artifact | Supported responsibility | Boundary retained |
|---|---|---|
| Parts API and mapping implementation | Delivered source-to-entity mapping consumed by an application | Did not own every downstream use of the data |
| Supplier-scoped identity decision documented for review | Explained the identifier rule and implemented the agreed mapping | Domain approval was not Yuri’s sole decision |
| Mapping regression tests and exception report | Checked supplier-scoped identity cases and reported the missing warehouse record | Did not prove all source facts were correct or complete |
| Vocabulary-change review note | Contributed implementation impact and consumer questions | Did not own ontology governance or production service operation |
The completed replacement statement reads: “Built a source-to-entity mapping and API for an internal parts catalog using supplier-scoped identifiers. Added mapping regression tests and reported unresolved warehouse fields for review. Contributed implementation-impact notes for vocabulary changes. The domain reviewer approved semantic definitions, and the platform team operated the graph service.”
Yuri’s completed search decision is to use these artifacts when discussing mapping, data integration and graph-consuming services. A position requiring reviewer-of-record authority or senior biological knowledge would need evidence outside this supplied packet. The example does not decide whether Yuri qualifies for a particular vacancy.
The unsent interview question reads: “Which semantic decisions would this opening own directly? Who approves a new term or an identity mapping, who resolves unmatched source records, and who maintains the graph service after a model change? I would like to distinguish the mapping work from governance and operational authority.”
Yuri can now explain why the two 07 records stayed separate, how the missing warehouse reached review and what implementation impact Yuri identified in the proposed vocabulary change. Those are concrete engineering contributions within the supplied history. It also gives the interviewer specific evidence to probe: an identity rule, an exception, a test and a proposed model change’s implementation impact. No application, private data or graph operation was performed for the example.
Choose the role by its meaning, mapping and maintenance work
Read the semantic artifacts, production duties and approval boundaries together. A role centered on ontology governance differs from one centered on ingestion and retrieval, even when both involve knowledge graphs. A familiar backend stack can be relevant, but it does not establish ownership of domain meaning.
Browse recent roles on LandOffer.ai, select one posting and prepare a mapping decision plus its source and review record. Compare that evidence with the role’s modeling, data-quality and maintenance duties. Keep location and appointment terms beside that comparison, and leave unsupported governance or production claims out of the application.
Sources and Further Reading
- Altos Labs Senior Knowledge Engineer, Ontology and Data Standards contract role, public responsibilities checked October 22, 2026.
- Encora career-board Senior Data & Knowledge Engineer posting, body names Coforge and specified Latin American locations; checked October 22, 2026.
- W3C RDF 1.1 Primer, Working Group Note, June 24, 2014.
- W3C SPARQL 1.1 Query Language, Recommendation, March 21, 2013.
- W3C OWL 2 Primer, Second Edition, Recommendation, December 11, 2012; references checked October 22, 2026.