LandOffer
Job search
Data Analyst Portfolio: Connect SQL, Data Checks, and a Dashboard to One Decision
Build a data analyst portfolio around one decision. Connect a public snapshot, checked SQL, explicit metrics, a readable dashboard and a bounded memo.
A data analyst portfolio should let a reviewer follow one decision from the question to the data, SQL, checks and dashboard. Define the metric and its unit, keep the query and source snapshot available, and write a short memo explaining what the result supports. A finished chart can show the finding; the surrounding evidence should show why the finding is trustworthy and where the decision must stop.
LandOffer publishes this guide and offers job-search tools. We created an original local analysis of public MTA estimates, checked the SQL output and exported a dashboard. Zinnia, the analyst described below, is fictional; the dataset and reported query results are real public inputs and local observations. This is not a production report or a hiring-outcome study. Start with recent roles on LandOffer and choose the analytical responsibility your sample needs to demonstrate.
Give the project a question and a decision boundary
“Analyze transit data” leaves too many choices unexplained. “Should this sample briefing show separate weekday and weekend baselines?” supplies a question the available daily data can answer. It also defines the deliverable: a comparison and a short interpretation, rather than a collection of unrelated charts.
Zinnia's original exercise uses estimated systemwide Subway rides for August 2026. She wants to decide how to present a descriptive baseline in a fictional planning briefing. She does not have station-level demand, hourly patterns, staffing constraints or a record of an actual stakeholder decision. Those omissions prevent the project from supporting a service-allocation recommendation.
A focused question can demonstrate analytical work. Selecting a unit, checking coverage, writing SQL and explaining a result are inspectable contributions. Do not invent a business impact to justify them. A candidate can describe what the analysis established without claiming that an employer changed operations or saved money.
Read the target job's responsibilities before choosing the project. A reporting role may need clear metric definitions and repeatable checks. An investigation role may need competing explanations and an uncertainty account. A predictive role may need a separate modeling example. The analyst and scientist search-track guide explains why shared tool names do not make those responsibilities interchangeable.
Establish the source, version and row grain
The current MTA Daily Ridership and Traffic dataset describes daily systemwide estimates and exposes Date, Mode and Count. Its public page was updated October 13, 2026 when checked. A search result also surfaced the older daily-ridership dataset, which is static and points readers to this replacement. Using the older result as a current feed would conceal a source change.
We downloaded a public snapshot on October 14 and retained its hash and source address. It contained 18,201 records across nine modes, with dates extending through October 12. The analysis selects only Mode = Subway and August 1 through August 31, 2026. The resulting grain is one Subway observation per calendar day.
Count cannot be treated as the same unit across every mode. The source covers ridership and traffic; adding all modes would mix different measures. Our selected metric is estimated Subway rides per observed day. It is not a count of unique people, and it is not the number of rides at an individual station.
The MTA overview explains that recent estimates may be revised and can differ from official totals published elsewhere. Keep an as-of date with the sample. If you refresh the data, retain a new snapshot and rerun the checks instead of silently replacing the input beneath an old chart. The public page's license field is unspecified; this exercise makes no legal determination about reuse rights.
A source note should make these choices recoverable. Record the dataset, download date, period, row unit and mode filter, along with the measures you excluded. That note helps a reviewer distinguish data you collected yourself from a public dataset you analyzed. The source authorship remains with MTA; selecting and checking the analysis is the candidate's contribution.
Make the data checks part of the result
The selected August snapshot contains 31 rows and 31 distinct dates. All 31 calendar days are present. The selected counts are non-null, numeric and nonnegative, and no duplicate selected dates were found. These are actual local checks of the saved subset, not a claim that every record in the entire public dataset is correct.
| Check | Actual selected-subset result | Why it matters |
|---|---|---|
| Date coverage | 31 of 31 August dates | The mean uses a complete month in this snapshot |
| Selected-date uniqueness | 31 distinct dates | Each day contributes once |
| Count validity | No null or negative selected counts | Missing values are not silently treated as zero |
| Mode boundary | Subway only | Ridership is not mixed with other modes' traffic measures |
Describe what happens when a check fails. A missing day should trigger a coverage warning and a decision about whether the period is usable. A duplicate should be investigated before summing. A missing count should remain missing until its meaning is established. Filling a blank with zero would change the metric from “observed average” to an assumption about an unobserved day.
For this exercise, no such repair was needed in the selected subset. That is still a useful result when the checks are documented. Do not manufacture a dirty-data problem to make the portfolio sound more sophisticated. You can add a clearly labeled synthetic failure example to demonstrate a check, but keep it separate from the actual source records.
The data analyst resume guide shows how metric definitions and query reconciliation can inform a concise resume account. The portfolio should preserve the longer evidence: source, checks, SQL and interpretation. A resume bullet does not need to carry the whole audit trail, but it must remain true when read without that trail.
Show the SQL that produces the displayed metric
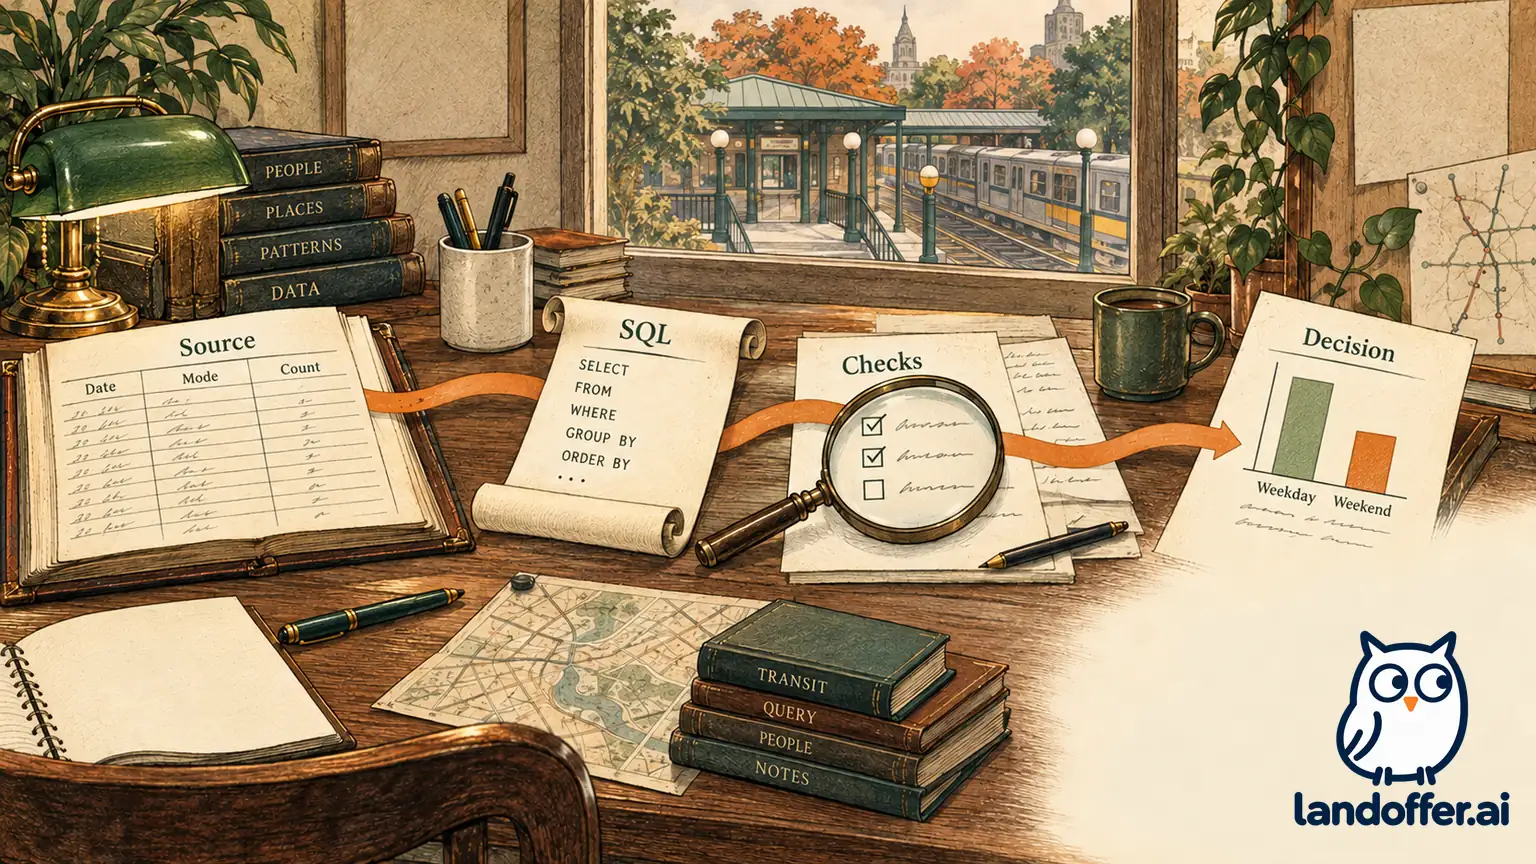
The saved SQLite query groups selected days into weekdays and weekends using the date. It reports observed days, total estimated rides and average estimated rides per observed day. We executed it locally, then reproduced the same output by loading the saved CSV into a fresh in-memory database.
Here is the central grouping and average:
SELECT
  CASE
    WHEN strftime('%w',date)
      IN ('0','6')
      THEN 'Weekend'
    ELSE 'Weekday'
  END AS day_type,
  COUNT(*) AS observed_days,
  ROUND(AVG(count),2)
    AS rides_per_observed_day
FROM ridership
WHERE mode = 'Subway'
  AND date >= '2026-08-01'
  AND date < '2026-09-01'
GROUP BY day_type;
The full saved query also returns the summed estimates and orders the output. SQLite's aggregate documentation distinguishes counting rows from counting non-null values and explains that AVG uses non-null inputs. That is why coverage and count validity are checked before interpreting the average. The query's successful execution cannot supply a missing metric definition.
| Day type | Observed days | Total estimated rides | Estimated rides per observed day |
|---|---|---|---|
| Weekday | 21 | 78,979,912 | 3,760,948.19 |
| Weekend | 10 | 24,682,486 | 2,468,248.60 |
The retained snapshot and executed query support these values. Weekdays and weekends have different numbers of observations, so comparing their monthly totals alone would answer a different question. The per-day mean makes the denominator explicit. It remains an unadjusted descriptive average; the exercise does not control for events, service changes or other influences.
The date grouping is also a definition choice. Here weekday means Monday through Friday, with no separate holiday category. If a real decision needs holidays treated differently, establish that rule and revise the query and chart together. Do not call this simple classification an adjusted demand model.
Build a dashboard that preserves the query's meaning
The original local dashboard presents two bars, the period, the selected mode, observed-day counts and the exact SQL results. The bars use a zero baseline and a common scale. Their labels round the averages to 3.761 million and 2.468 million; the table preserves the more precise computed values.
The chart is an export generated with standard plotting tools and displayed in an authored HTML page. We opened the dashboard locally and checked that its values matched the query record. It is not a tested Tableau workbook, a public Tableau profile or a screenshot from a commercial reporting system. Keep that implementation distinction visible when describing the work.
A dashboard title should identify the question or metric. “Transit insights” tells the reader little. “Separate the weekday and weekend baseline?” identifies the decision being considered, while the subtitle supplies the mode and month. A caption or nearby note can explain whether the figures are estimates and when the source was downloaded.
Make the display's claim easy to inspect. Keep the source, filters and important exclusions visible. If an interactive filter changes the population, update the denominator and labels with it. A chart that appears unchanged after a filter can mislead even when the underlying query is correct. Our dashboard is a static local sample, so it makes no interactive-filter claim.
Write the completed decision memo
Zinnia's fictional briefing ends with a bounded conclusion:
Decision: Present separate weekday and weekend descriptive baselines for this sample briefing. The saved August estimates average about 3.761 million Subway rides per weekday and 2.468 million per weekend day. Keep the observed-day counts beside the comparison. Do not use these systemwide figures to allocate station staff or infer hourly demand.
The next evidence request follows directly from the boundary: station or location detail, hourly patterns and operating constraints would be needed before a real allocation decision. The sample does not say those records exist or that a team approved the recommendation. It records what additional information the current data cannot supply.
| Statement | Evidence available | Completed decision |
|---|---|---|
| The two day groups have different descriptive means | Saved subset, SQL output and chart | Show separate baselines in the sample briefing |
| A particular station needs more staff | No station, hourly or staffing data | Do not make the allocation recommendation |
| A policy caused the difference | No causal design or comparison controls | Do not attribute a cause |
| The dashboard improved operations | No adoption or outcome record | Describe the deliverable and checks only |
This memo gives the portfolio a finish. The analyst has produced an interpretable result and a decision about its use. Leave the operational question open until the necessary data and constraints are available. If later evidence supports a broader decision, document the new inputs and review separately.
Package the work and verify the actual destination
Keep the selected CSV, SQL, check record, source receipt, chart and memo together. Add a short README naming the environment and commands needed to reproduce the result. A reviewer should be able to connect the displayed value to its computation without guessing which notebook or file produced it.
For a public dashboard, consider the exposure implied by the host. Tableau describes Public as a free platform for public visualizations, and its workbook publishing guide warns that published workbooks and data are accessible to anyone. That guide also distinguishes local saving in Desktop Public Edition. Verify the current product and sharing behavior before choosing a delivery route.
Our sample stays local. It demonstrates authored exports and reproducible analysis, while external hosted access remains untested. Before an actual application, follow the employer's instructions, open the final sample link signed out and check linked files. Preserve an authorized readable fallback when useful. A local HTTP response cannot prove that an employer can open a public destination.
Describe the contribution precisely: analyzed a specified public snapshot, defined the day-based metric, checked coverage and uniqueness, reproduced the SQL and documented the decision limit. Keep dataset authorship, plotting libraries and fictional stakeholder context separate. Choose a responsibility from recent roles on LandOffer, then lead with the sample whose query and memo demonstrate that work.