LandOffer
Job search
CodeSignal Machine Learning Framework: Prepare for Fundamentals, Data Manipulation, and Implementation
Separate ML concepts, data transformations and algorithm implementation, practice with clear contracts, and verify the rules attached to your actual assessment.
Prepare for CodeSignal’s Machine Learning Framework by separating three abilities: explaining fundamental concepts, manipulating data accurately and implementing an algorithm from a specification. Then check which assessment you have actually been invited to take. Use the framework to organize study, then use your invitation to confirm duration, environment and allowed resources.
A strong preparation session should produce something you can explain: a conceptual distinction, a correct transformation with edge cases, or an implementation whose behavior matches a written contract. Keep applications organized through LandOffer.ai while reserving assessment-specific questions for the instructions and recruiting contact associated with that request.
This guide reviews public documentation checked October 22, 2026. The two exercises below are original teaching examples with invented inputs, not CodeSignal questions, reported candidate tasks or assistance for an active assessment. No private assessment or account was accessed.
Use the framework as a skills map
CodeSignal’s Machine Learning Framework resource page describes skills including cleaning data, evaluating models and connecting machine-learning pipelines to business metrics. The linked technical brief organizes fundamentals, data manipulation and algorithm implementation. It says the framework can support different delivery methods, including screening assessments and technical interviews.
The public brief specifies a module structure, timing and score range for its framework-based evaluation design. Treat those as specifications in that document, rather than promises about every current invitation. Do not schedule your session around a number found in a search snippet without checking the information for your own assessment.
CodeSignal’s current certified-assessment overview lists Machine Learning Core Assessment and links to the framework. That establishes a relationship between the public research document and a named assessment offering. It does not identify an employer’s custom evaluation merely because the job title includes “machine learning.”
Record the exact assessment name, employer, invitation deadline and instructions you received before deciding what to study. Leave unknowns blank or marked unresolved. A backend engineer moving into ML may need conceptual review; a researcher accustomed to notebooks may need more practice translating a compact specification into ordinary functions. Choose study work based on that gap.
Fundamentals: explain the reasoning before naming the model
The brief includes topics such as regularization and overfitting. Prepare to explain what changes when an assumption changes, rather than memorizing a list of algorithm names. A useful study answer connects the objective, available data and evaluation method.
For example, consider an invented experiment where training error falls after making a model more flexible, while validation error rises. The defensible observation is that training fit improved and held-out performance worsened in that experiment. It does not prove that the new model will always be worse, identify the only possible cause, or establish that adding more training iterations fixes the problem.
Ask what data split was used, whether the comparison used the same metric and whether preprocessing respected the split. The official scikit-learn common-pitfalls guide explains that learning preprocessing from test data can leak information and produce optimistic performance estimates. Learn transformations on training data, then apply the learned transformation consistently to other data.
As a personal practice check, explain why calculating a normalization constant from the full dataset before splitting can contaminate an evaluation. You do not need to invoke a large library to express the information boundary. Identify what is learned, which observations it may use and what remains held out.
Keep the answer proportional to the question. An explanation of overfitting should address generalization and evidence; a question about an algorithm’s mechanics needs its actual computation. Connect the vocabulary to the observed result and explain whether the evaluation procedure supports the comparison.
Data manipulation: turn prose into an explicit contract
Before coding, define the row, missing-value rule, ordering and duplicate policy so the implementation preserves the intended data rather than merely producing a result. These are implementation decisions with visible consequences. A solution can run without errors and still violate the requested behavior.
The following exercise deliberately uses tiny synthetic records. Its purpose is to make every retained and discarded value explainable. It is not a realistic sensor pipeline, an ML dataset or a prediction task.
Original exercise one: Given ordered pairs of sensor identifier and reading text, trim whitespace and ignore the exact missing marker NA. Retain the latest nonmissing integer for each identifier. A later missing value must not erase a valid reading. Return pairs sorted alphabetically by identifier. Assume identifiers are nonempty strings and every nonmissing reading is valid integer text.
Input, in order:
(rack-a, "6")
(rack-b, " NA ")
(rack-a, "10")
(rack-c, "8")
(rack-b, "4")
(rack-a, " NA ")
A complete Python implementation is:
def latest_readings(rows):
    values = {}
    for sensor, raw in rows:
        text = raw.strip()
        if text == "NA":
            continue
        values[sensor] = int(text)
    return sorted(values.items())
The completed output is [("rack-a", 10), ("rack-b", 4), ("rack-c", 8)]. The first rack-b entry is ignored; its later value is retained. The second valid rack-a reading replaces its first value. The final missing entry leaves that value unchanged.
If you calculate a mean of the three retained readings, it is 22 / 3, approximately 7.3333. That is a descriptive result for these invented values, not a model score. The mean uses three retained identifiers, not all six input rows.
An empty input returns an empty list. An identifier with only missing entries is absent. Whitespace around " 5 " is removed before conversion; "na" is not the defined marker. Invalid nonmissing text lies outside this exercise’s contract and would need an explicit error policy in a broader implementation.
These details reveal useful review questions: did you accidentally keep the first occurrence, count missing rows, erase an earlier value, or return dictionary insertion order instead of the requested sorted order? Explain which line enforces each requirement. Correctness comes from the contract, not from the small size of the example.
Implementation: make the algorithm’s choices visible
Algorithm implementation adds a different burden: you must translate a mathematical or procedural description into consistent code. Calling a convenient model API can conceal whether you understand distance, aggregation, tie handling and the difference between fitting and predicting.
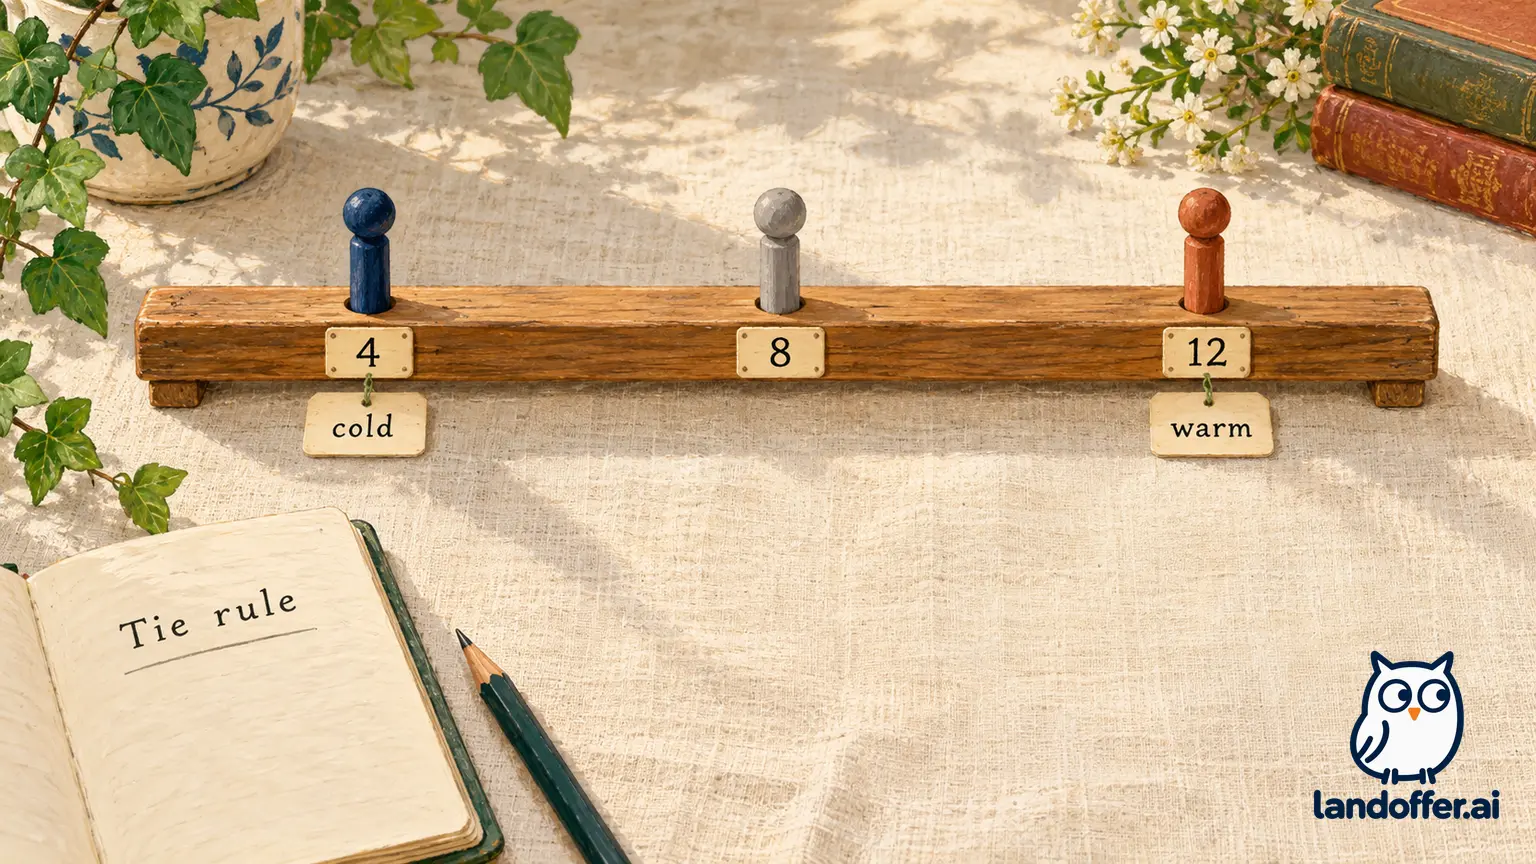
Original exercise two: Build a simple one-dimensional nearest-centroid classifier from named groups of numeric training values. Each group’s centroid is its arithmetic mean. Assign each query point to the closest centroid by absolute distance. On a tie, choose the alphabetically first group name. Reject an empty group collection or any group with no values. Assume finite numeric inputs and nonempty string labels.
Use training groups {"cold": [2, 6], "warm": [10, 14]} and query points [3, 8, 13]. The labels are arbitrary teaching names, not categories learned from a real dataset.
def nearest_centroid(groups, points):
    if not groups or any(not values for values in groups.values()):
        raise ValueError("Each named group must contain a value")
    centers = {name: sum(values) / len(values)
               for name, values in groups.items()}
    return [min(centers, key=lambda name:
                (abs(point - centers[name]), name))
            for point in points]
The completed centroids are cold = 4 and warm = 12. Point 3 is one unit from the first and nine from the second, so its label is cold. Point 8 is four units from each; the declared alphabetical rule selects cold. Point 13 is nearest warm. The output is therefore ["cold", "cold", "warm"].
This is nearest-centroid classification, not nearest-neighbor voting or an iterative clustering procedure. The code calculates one center per existing labeled group; it does not search individual training samples or learn an unspecified number of clusters. State that distinction when explaining your implementation.
For valid groups and no query points, the output is empty. An empty group raises the specified error before prediction. The comparison orders candidates by distance first and label second, so equal distances resolve alphabetically rather than by dictionary insertion order. If the contract instead required a different tie policy, the implementation would need to change; dictionary order should not silently decide it.
The routine uses built-in Python operations and no ML package. That is a teaching choice, not a statement that every CodeSignal assessment requires Python or forbids libraries. Confirm the actual permitted language, environment and dependencies from the assessment instructions.
Review what the small examples do and do not prove
Check correctness against the declared contract before optimizing. In the reading routine, append another missing row for an existing identifier: the output should stay unchanged. Append a valid reading for that identifier: its value should change, while the other identifiers remain intact. This gives you a concrete way to reason about state updates without relying on one successful demonstration.
For the centroid routine, reverse the order in which the two group names appear in the input dictionary. The midpoint result should remain the same because the tie policy uses alphabetical labels. By contrast, changing the training values can change the centers and therefore the predictions. A useful explanation separates changes that should matter from changes that should not.
Discuss computational cost in terms of these actual implementations. The reading routine scans the rows and sorts the retained identifiers. The centroid routine first computes group means, then compares each query against each center. Neither explanation requires claiming that the algorithm is optimal for every input size or that this cost matches an assessment’s hidden constraints.
Finally, identify missing real-world responsibilities. The reading routine has no timestamp ordering, access control or data-quality monitoring. The classifier has no evaluation split, feature scaling, confidence estimate or deployment interface. Adding those responsibilities would require a new specification. Keeping that boundary visible helps you explain a small exercise accurately instead of presenting a few correct outputs as evidence of a production-ready ML system.
Match the study session to the weakness
Use the two exercises to identify what needs attention before adding more topics. If the data routine is difficult, practice parsing and state updates separately. If its output is easy but the centroid tie is unclear, work through the computation by hand before translating it into code.
For a focused study session, write the contract, predict the output, implement the routine and compare the result with your reasoning. Then change one condition: append a missing reading, remove a group’s values, reorder labels or query the exact midpoint. Explain whether the output should change and why.
This approach also gives you a more useful progress record than “finished ten questions.” Record the actual mistake and correction: “I erased the latest valid reading when a missing row appeared; now missing rows leave state unchanged.” Such a note identifies a repairable gap without pretending that a self-made exercise predicts an assessment result.
Keep an additional conceptual explanation alongside the code. A correct small classifier does not establish that you can evaluate a deployed model, handle changing distributions or choose a business metric. Those are separate learning goals, and a compact practice example should not be presented as production experience.
Confirm timing and resources before starting
The current Taking an assessment guide says the information page shows duration, question count and instructions, with assessment-specific time limits set by administrators. It also warns that an assessment must be completed in one sitting. Use that information to reserve uninterrupted time before starting.
The certified-assessment rules page points candidates to the IDE’s Rules section and distinguishes basic syntax lookup from outside help with solution logic. Read the rules attached to your actual request; public preparation material is not permission to consult answers during an assessment.
CodeSignal separately announced agentic coding assessments in its March 2026 product updates. Those offerings involve working with an agentic helper and explaining the work. Their existence does not grant AI permission for ML Core, a custom ML evaluation or another assessment. The current taking guide also describes Cosmo as company-configurable.
Before starting the timed session, confirm the assessment name, displayed time limit, allowed resources and required setup; resolve unclear instructions while there is still time to ask. Keep private invitation content out of public forums and AI chats. Continue reviewing recent roles on LandOffer.ai alongside preparation, with the framework serving as a study map rather than a promised route to a particular score or job.
Sources and Further Reading
- CodeSignal: Machine Learning Framework and public technical brief — skills scope and framework specifications.
- CodeSignal: What are certified assessments? — named ML Core offering.
- CodeSignal: Taking an assessment — current invitation information and session instructions.
- CodeSignal: Certified-assessment rules — resource boundaries.
- CodeSignal: March 2026 updates — separate agentic offerings.
- scikit-learn: Common pitfalls — training/test separation and preprocessing. Sources checked October 22, 2026.